×
Our valued Brands & Agencies







Custom NLP development services built around your data
As a custom NLP development company, we design language solutions around your documents, conversations, and domain vocabulary instead of forcing a generic model onto your business. Our engineers combine classical NLP techniques, transformer models, and large language models to choose the right approach for each use case.
Custom NLP Model Development
We build and fine-tune NLP models on your own data, from compact transformer models like BERT to open-weight LLMs. Each model is evaluated against your accuracy, latency, and budget targets, and can run in your cloud or on-premise when data must stay in-house.

Text Classification & Sentiment Analysis
We create classifiers that sort tickets, emails, reviews, and reports by topic, intent, urgency, or sentiment. Teams use them to route support queries automatically, track customer opinion across channels, and catch emerging issues before they escalate.

Named Entity Recognition & Information Extraction
Our NER and extraction pipelines pull names, organizations, dates, amounts, clauses, and domain-specific entities from unstructured text and turn them into structured records your systems can use, with validation rules that flag low-confidence results for human review.

Document Processing & Summarization
We automate the reading of contracts, invoices, claims, clinical notes, and research files. Our document pipelines classify incoming files, extract key fields, and generate concise summaries, reducing the manual review that slows down document-heavy teams.

Semantic Search & Topic Modeling
We develop search that understands meaning, not just keywords, using embeddings and vector databases. Topic modeling reveals recurring themes across large text collections, and for knowledge assistants we pair search with RAG development to ground answers in your own content.
Conversational NLP & Chatbots
We engineer the language layer behind chatbots and virtual assistants, including intent detection, entity capture, dialogue context, and escalation logic. For complete assistant builds, our AI chatbot development team takes the solution from conversation design to launch.

Speech & Voice NLP
We combine speech-to-text, text-to-speech, and NLP to process calls, meetings, and voice commands. Typical work includes transcription with speaker labels, call analytics, and spoken-language assessment, while our AI voice agent development team handles real-time voice automation.

Multilingual NLP & Translation
We build NLP solutions that work across languages, with language detection, machine translation, and cross-lingual search, so a single system can classify, extract, and search content in every market you serve without separate pipelines for each language.
Accelerating enterprise transformation through AI and digital engineering.
20+
Years in Business
350+
IT Professionals
ISO 9001 Certified
NASSCOM & STPI Accreditation
NASSCOM & STPI Accreditation
750+
Clients Worldwide
1800+
Projects Executed
Industries We Serve
As a natural language processing development company, we adapt every NLP solution to the vocabulary and compliance needs of your industry, from clinical notes in healthcare and contracts in professional services to transaction narratives in banking and customer conversations in retail.
Automotive
Real Estate
Entertainment
Retail & Ecommerce
Healthcare
Transportation
Manufacturing
Travel & Tourism
Professional Services
Software Vendors
Banking & Finance
Education
Transformer Models & LLMs
Transformer models power most modern NLP work. We use encoder models such as BERT for fast classification and extraction, and large language models for summarization, reasoning, and generation, often combining both to balance accuracy with cost. Our LLM development team handles model selection, prompting, and evaluation.
Machine Learning
Classical machine learning still earns its place where data is limited or decisions must be explainable. We apply ML algorithms to text classification, anomaly detection, and ranking, drawing on our machine learning development practice for feature engineering and model tuning.
Deep Learning
Neural networks let NLP models learn context, tone, and long-range meaning in text. Our deep learning development experience covers sequence models, transformers, and speech architectures trained and optimized for production workloads.

Natural Language Understanding (NLU)
Natural language understanding helps systems identify the intent, context, and sentiment in what people write or say. We build NLU components that turn unstructured messages into clear signals for routing, automation, and analytics.

Natural Language Generation (NLG)
Natural language generation converts data and documents into readable text such as reports, summaries, and customer replies. We pair NLG with generative AI models and guardrails so generated text stays accurate, on-brand, and traceable to its source.
Speech Recognition
Speech recognition models transcribe audio across accents, dialects, and noisy environments. We tune ASR for your domain terms and connect transcripts to NLP pipelines for search, analytics, and hands-free interaction.
Text Analytics
Text analytics surfaces trends, sentiment, and key entities across large volumes of feedback, tickets, and reports. We build pipelines and dashboards that turn this text into insights your teams can act on for better planning and faster decisions.
NLP and language AI projects we have delivered
These projects show how our team applies speech recognition, conversational AI, and natural language querying to real business problems, from exam-style speaking evaluation to plain-English access to live operational data.
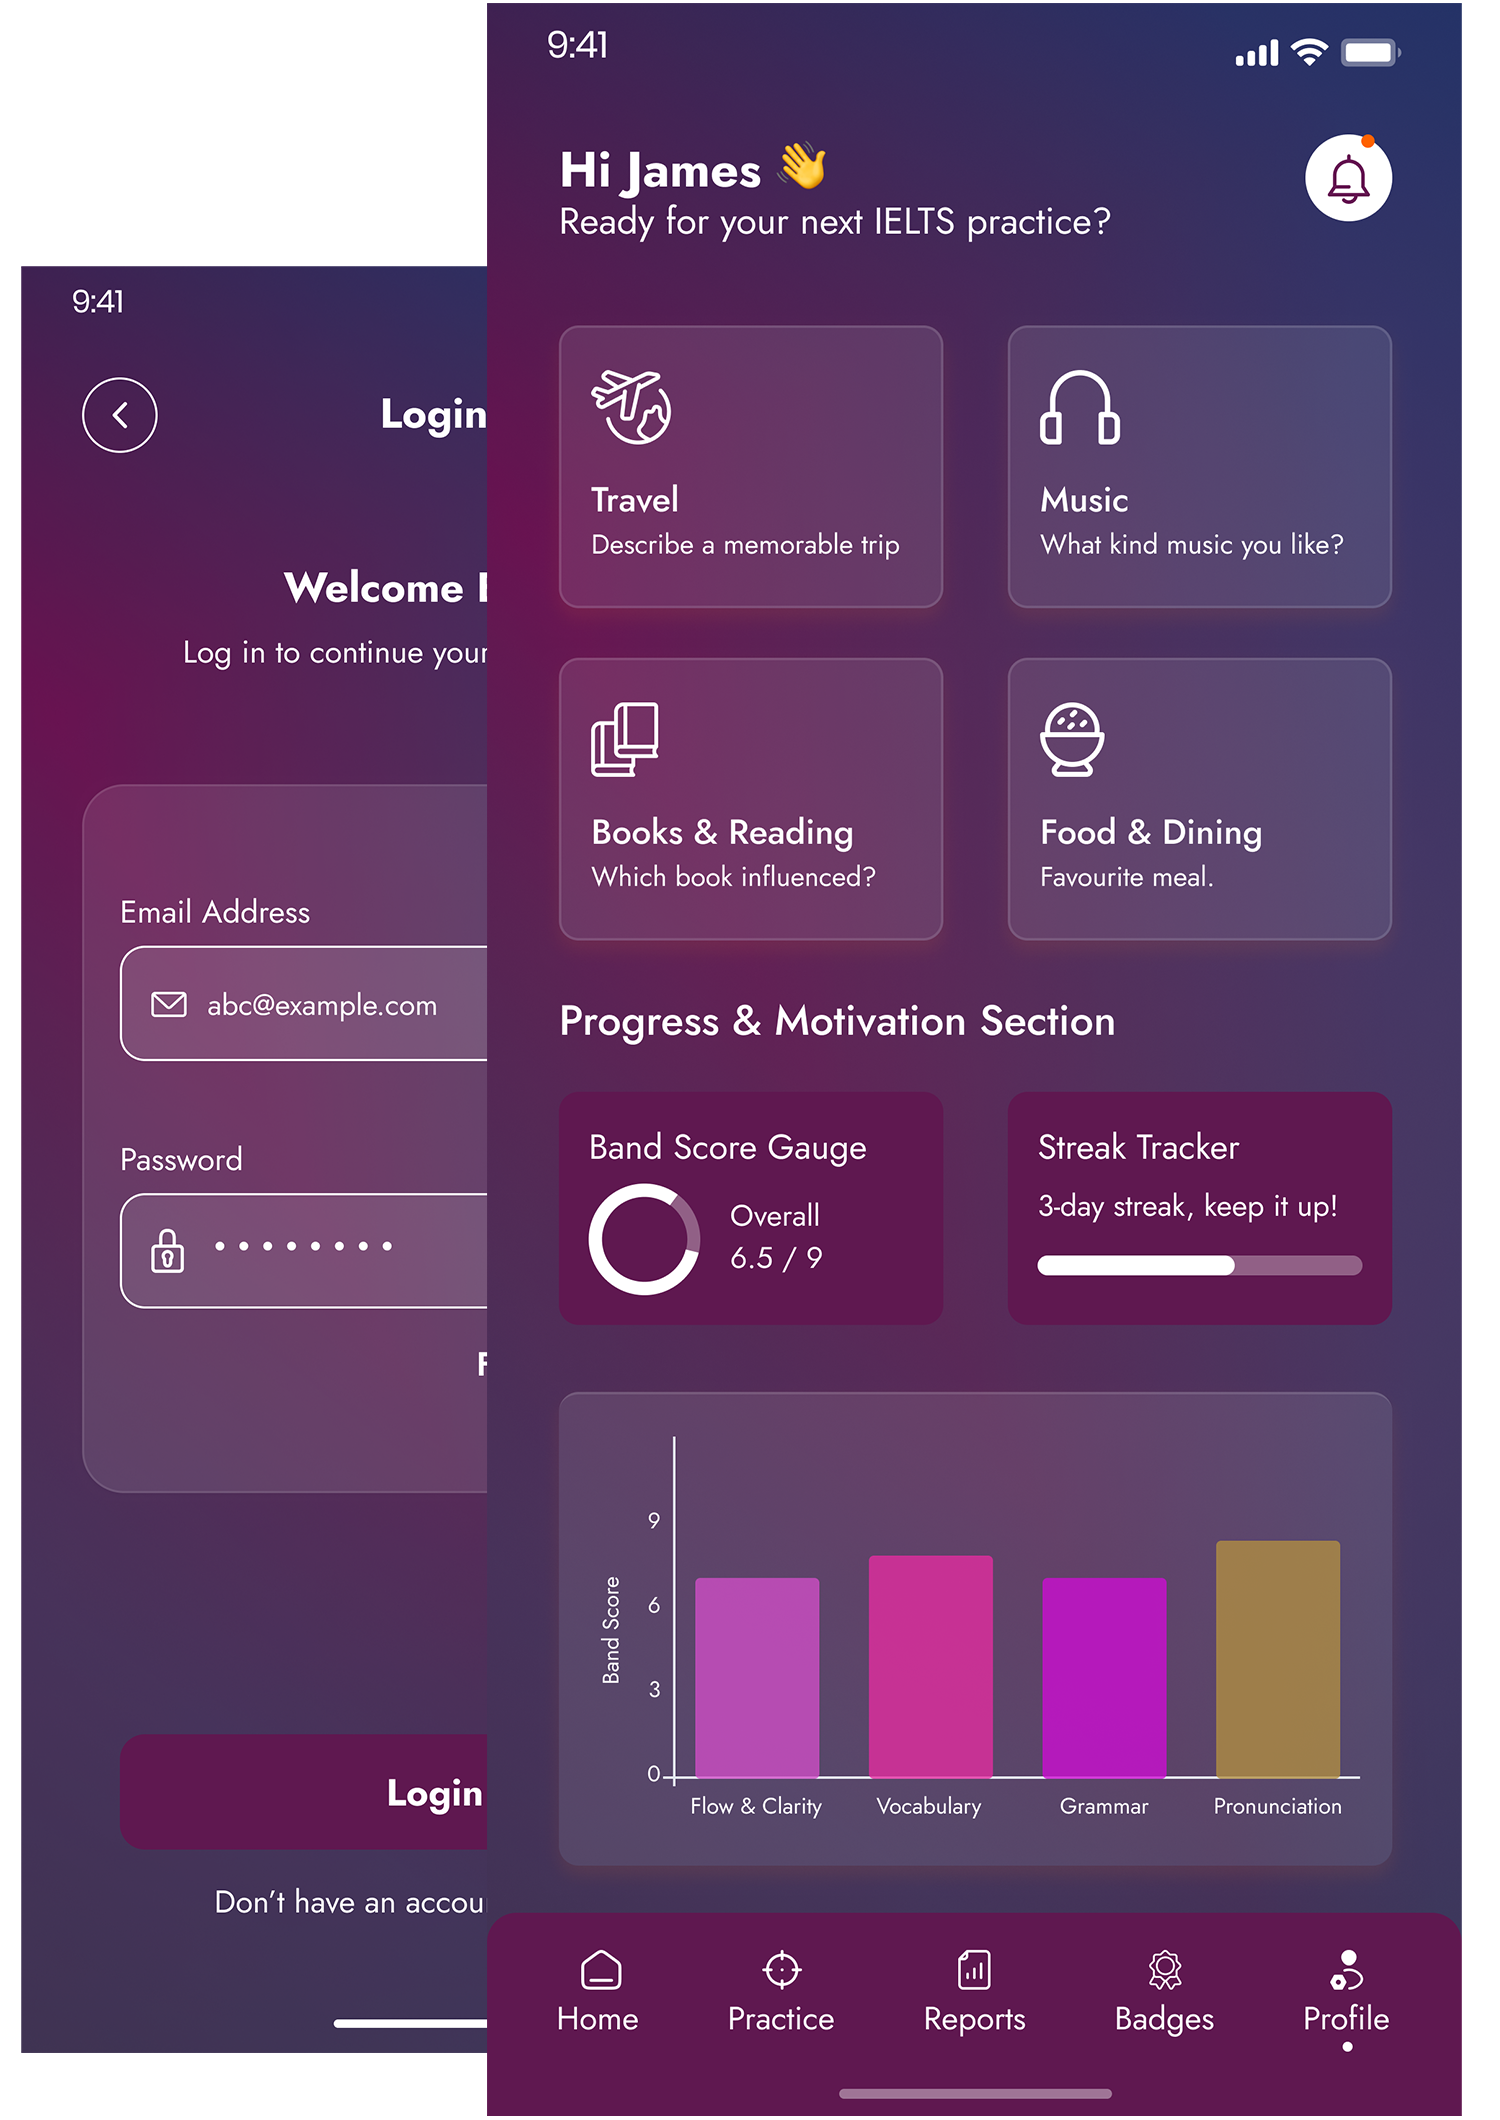
IELTS AI-Powered Speaking Evaluator
The Challenge
Human IELTS tutors cost $30 to $80 per hour and have limited availability. Generic speaking apps lack the authentic Part 1/2/3 exam structure, pronunciation feedback, and band-aligned scoring. Learners had no way to get unlimited, exam-style practice at scale.
Our Approach
We built a full-stack AI platform with a lifelike AI avatar examiner, using a LangGraph and Gemini conversation engine, Google Cloud TTS with viseme lip-sync, Faster-Whisper speech recognition, and a 6-layer evaluation pipeline that scores all 4 IELTS criteria within ±0.5-1.0 band accuracy.
The Result
- 1,000+ concurrent users with 2–3s response latency
- 10x lower cost than human examiners
- 6 AI microservices with model preloading
- No-code admin panel for quick content updates
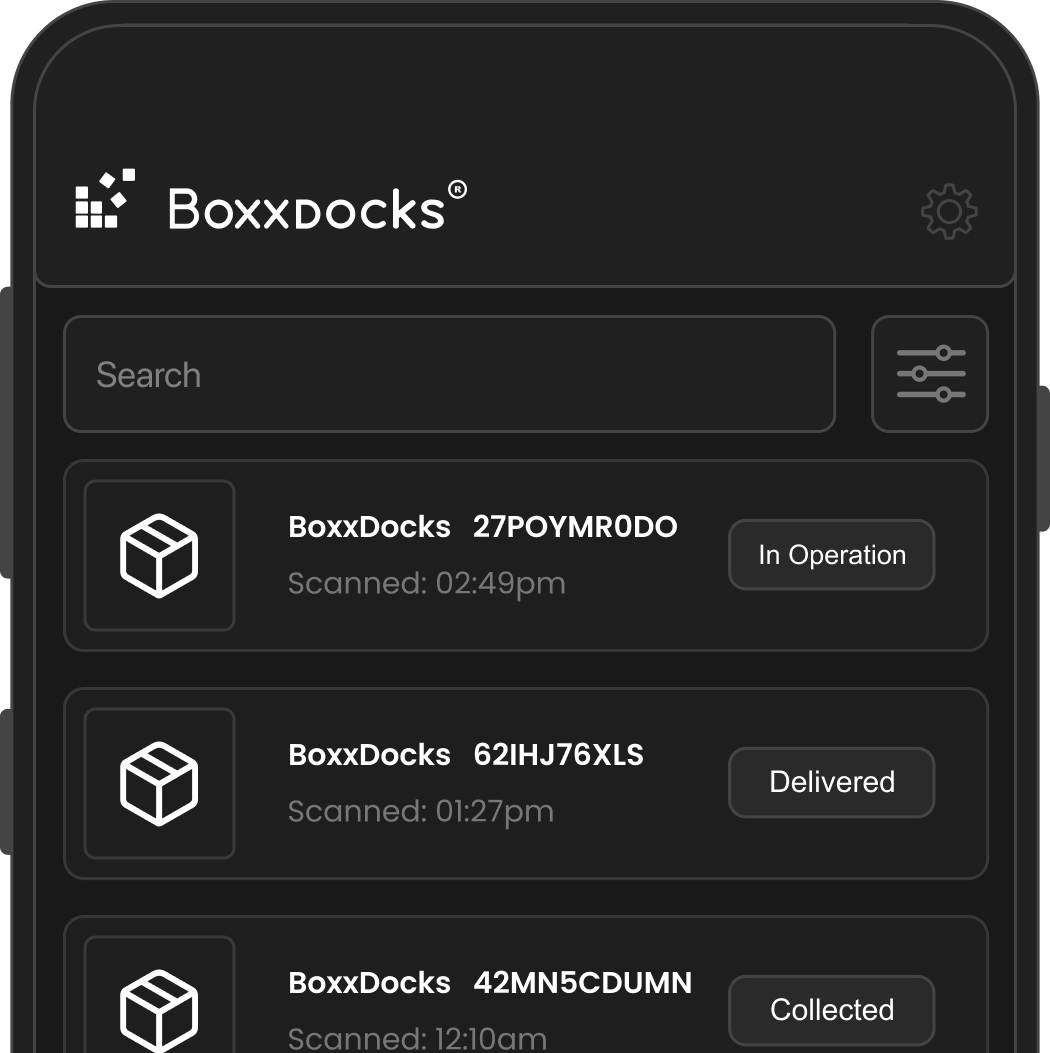
BoxxDocks AI Asset Tracking Platform
The Challenge
Asset tracking was manual, error-prone, and scattered across disconnected systems. The client had no central view of asset movement, no real-time location data, and no way to generate instant reports for multiple enterprise clients from one platform.
Our Approach
We built BoxxDocks as an AI-enabled asset lifecycle platform with QR/NFC scanning, real-time dashboards, geolocation tracking, and a RAG-powered conversational engine that lets users query live operational data in plain English instead of digging through dashboards.
The Result
- Real-time inventory tracking across warehouses, transit, and delivery
- AI query engine for natural language insights
- LLM-powered reporting with anomaly detection
- Complete audit trail with location, timestamp, and status
Health E Livin AI Wellness Platform
The Challenge
People struggling with mental health had no single place to access trusted information, take confidential assessments, and find providers without stigma or privacy concerns.
Our Approach
We built Health E Livin as an AI-powered mental wellness app with a conversational AI assistant, anonymous screenings, an evidence-based resource library, and geolocation-based provider discovery, all running on privacy-first cloud infrastructure.
The Result
- AI knowledgebase for natural language mental health support
- Confidential assessments with personalized wellness insights
- Location-based provider discovery for professional care
- Privacy-first architecture with encrypted data management
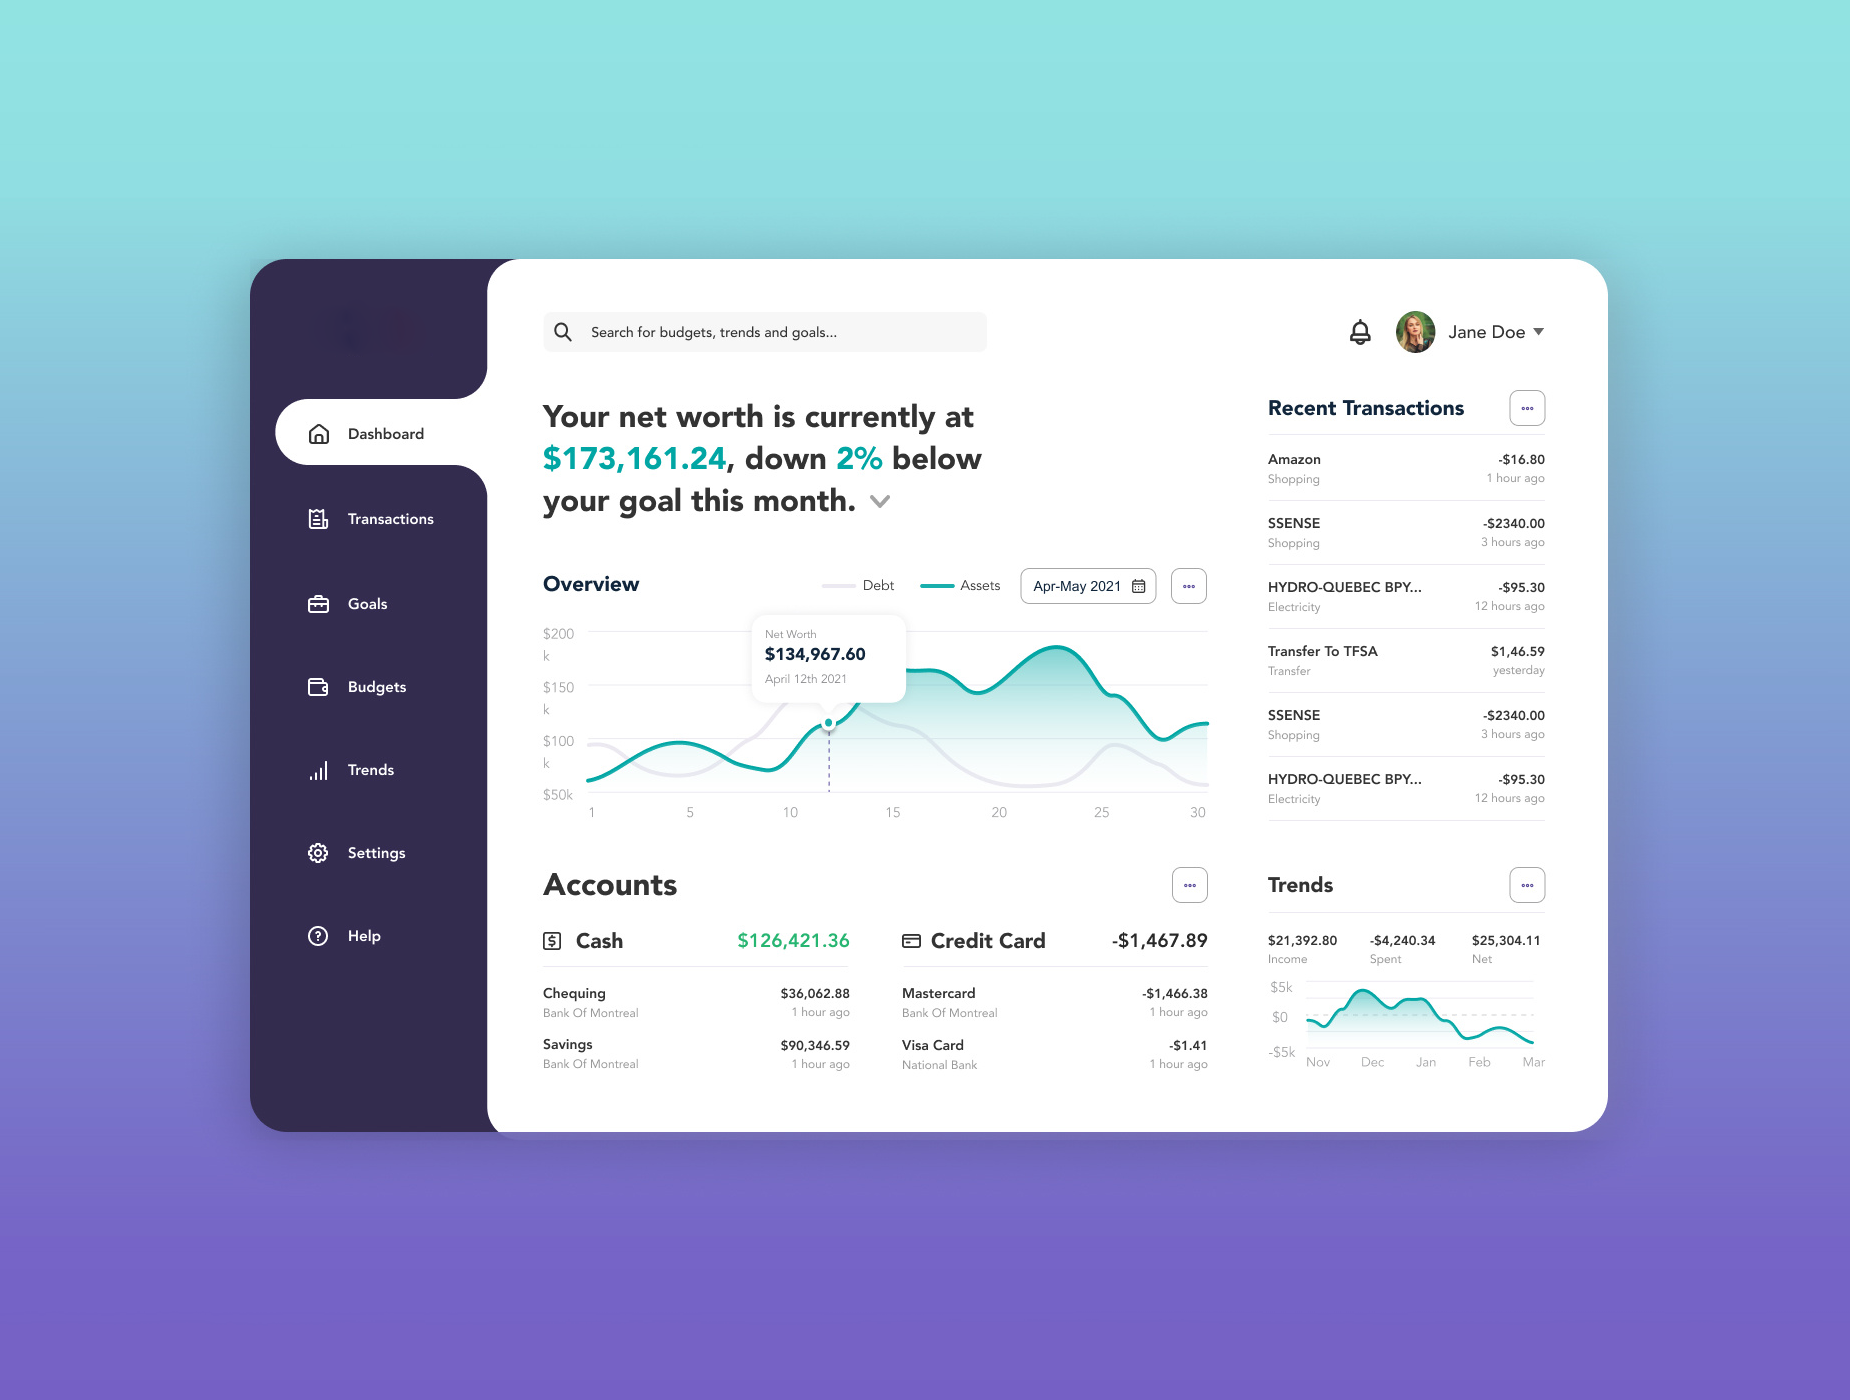
Parity AI AI Finance Platform
The Challenge
Personalized financial advice was expensive and limited to periodic meetings. Users had no way to bring banking, investments, debt, and insurance into one platform with real-time, AI-driven guidance.
Our Approach
We built Parity AI as an always-on financial wellness platform. It securely pulls data from multiple sources, analyzes user behavior, forecasts outcomes, and delivers personalized recommendations through a conversational interface, acting as a digital financial advisor rather than a budgeting app.
The Result
- AI-powered financial planning across banking, investments, and debt
- Personalized recommendations based on life events and behavior
- Integrated financial education with actionable insights
Turn your text and speech data into business value
Planning a new language AI project or improving a model that is already live? Talk to our NLP development company about your data, use case, and goals, and get a practical roadmap from proof of concept to production.
Technology stack we use for NLP development
As an NLP development company, we select models, frameworks, and infrastructure based on your data, the languages you support, and where the solution needs to run, from open-source transformers to enterprise LLM platforms and MLOps tooling.
 Python
 Hugging Face
 PyTorch
 TensorFlow
 spaCy
 NLTK
 Scikit-learn
 Pandas
 Jupyter
 Databricks
 OpenAI GPT
 Claude
 Gemini
 Llama
 Mistral
 BERT
 LangChain
 LlamaIndex
 vLLM
 Google Cloud Speech-to-Text
 Azure AI Speech
 Resemble AI
 Rasa
 Dialogflow CX
 IBM watsonx Assistant
 Microsoft Copilot Studio
 Botpress
 Pinecone
 Qdrant
 Weaviate
 FAISS
 Elasticsearch
 PostgreSQL (pgvector)
 MongoDB
 AWS
 Amazon SageMaker
 Vertex AI
 MLflow
 Docker
 Kubernetes
 LangSmith
 Arize AI
Why choose Xicom as your NLP development company?
Clients choose our NLP development services because we pair 20+ years of software engineering with hands-on NLP and LLM expertise, delivering language solutions that are secure, measurable, and built to work with the systems you already run.
Delivering proven excellence for our clients
- Rated 4.8/5 on Clutch and GoodFirms, Top 1% on TrustPilot.
- 20+ years of digital engineering and AI-first innovation.
- 1,800+ projects delivered across 50+ countries.
- 350+ dedicated IT and AI professionals.
- End-to-end LLM and AI development for startups and enterprises.
- 100% customer satisfaction guarantee.
20+ Years of Expertise
Two decades of software and product engineering, now focused on AI solutions, help us build future-ready systems that deliver measurable business outcomes.
100% Transparency
We enable real-time progress tracking, clear communication, and structured reporting to maintain complete visibility across every stage of product development.
98% On-Time Delivery
With systematic project management and agile execution, we ensure consistent delivery of tailored solutions within agreed-upon timelines.
Strict NDA
We enforce strict NDAs, industry-approved encryption, and secure architectures, safeguarding confidentiality and data integrity across every engagement we undertake.
Flexible Engagements
Our engagement models cover scalable resource allocation, fixed scope delivery, and dedicated teams, adapting flexibly to your evolving business requirements.
24x7 Support
We offer round-the-clock support and continuous monitoring, ensuring faster issue resolution, system stability, and ongoing performance optimization for every project.
Our natural language processing development process
As a natural language processing development company, we put data quality and measurable accuracy first, with clear checkpoints so you know exactly how a model performs before it reaches your users.
-
Discovery & Data Audit
We define the use case, success metrics, and constraints, then review your text and speech data for volume, quality, and gaps.
-
Data Preparation
We clean, normalize, and label your data, with data annotation support where labeled examples are limited.
-
Model Development
We select, train, or fine-tune the right models and build the pipelines and APIs around them.
-
Evaluation & Testing
We test accuracy, bias, latency, and edge cases against real-world samples before sign-off.
-
Deployment & Monitoring
We deploy to your cloud or on-premise, then monitor for drift and retrain models as your data changes.
Engagement models for NLP development
As an NLP development company, we offer flexible engagement models to match your project's complexity, timeline, and budget. Choose a fixed-price build, a dedicated NLP team, or a time-and-material model for requirements that evolve as you learn from your data.
Ideal for NLP projects with well-defined requirements, such as a document classifier or extraction pipeline, with clear deliverables and predictable costs.
- Transparent pricing with no hidden fees
- Agreed scope, milestones, and timelines
- Milestone-based progress tracking
- Lower financial risk with a predictable budget
Best for long-term NLP programs that need a focused team of engineers working on your roadmap. If you only need specialists inside your own team, you can also hire NLP engineers directly.
- Scalable team size as your needs change
- Full control over priorities and process
- Close collaboration with your in-house team
- Faster delivery with a stable, dedicated team
Suited to NLP projects where requirements evolve as you experiment, such as LLM pilots or research-led proofs of concept.
- Pay only for the hours used
- Freedom to change scope as results come in
- Continuous improvement between iterations
- Faster experimentation and time to market
Client testimonials and reviews showcasing the value we consistently deliver
Explore how our clients describe their journey with us, reflecting strong collaboration, effective execution, and consistent outcomes delivered across engagements. See how our delivery framework ensures consistency from initiation through to successful completion.
❝
Parity AI
We came to Xicom with an ambitious goal: make institutional-grade financial planning accessible to everyone through AI. Xicom went beyond the brief, blending conversational AI and predictive analytics into an effortless platform. Parity AI is exactly what we envisioned.
❝
RadioFX
Xicom took the time to understand what our stations and listeners actually need, building something tailored rather than generic. Live chat and polls are now core to how we connect with our audience — the app has become a true extension of our on-air presence.
❝
StudyBuddy
Xicom built exactly what our students needed: a secure space to connect, collaborate, and find tutoring support in one place. Their understanding of student behavior shows in how naturally everything fits together — StudyBuddy is something students genuinely rely on.
❝
BoxxDocks
Xicom helped us bring BoxxDocks to life exactly as we envisioned it. Their team understood the complexity of AI powered real-time asset tracking and delivered a platform that's both powerful and genuinely easy to use.
❝
TodayFit
We are very happy with their services. I cannot recommend them highly enough. The value, ability, and delivery that we have seen has been superb, and we look forward to continuing this relationship.
❝
SmartVend AI
Their team built SmartVend from the ground up, combining hardware integration, real-time inventory sync, and a centralized dashboard that completely changed how we operate. We couldn't have asked for a more capable technical partner.
❝
Tap Retail
Partnering with Xicom to develop our Tap Retail app and website was one of the best decisions we made. Their team demonstrated exceptional professionalism, technical expertise, and a deep understanding of our business goals.
❝
GoGmGo
Partnering with Xicom was a game-changer for us. They didn't just build software, they helped us redefine how we run our business. Their proactive support and deep domain knowledge gave us the confidence to innovate faster.
❝
DENVEN
Working with Xicom has been a transformative experience. Their team quickly understood our challenges and delivered a scalable, intuitive solution. I highly recommend Xicom to any organization seeking future-ready, high-performance digital products.
Top tech insights of our blog
Explore latest tech stories & News
✦ AI-First Company
Deep Insights into Emerging Technology and Innovation!
Stay ahead in the digital world with our latest insights covering AI trends, industry developments, and expert advice on building smarter businesses.
1800+
Projects
20+
Years Experience
Frequently Asked
Questions
What does an NLP development company do?
An NLP development company designs, builds, and maintains software that understands and generates human language. The work usually includes text classification, entity extraction, document processing, semantic search, chatbots, and speech analytics, along with the data preparation, model evaluation, and deployment needed to keep these systems accurate in production.
Why work with a custom NLP development company instead of using off-the-shelf tools?
Off-the-shelf NLP APIs work well for generic tasks but often struggle with industry vocabulary, internal document formats, and strict data rules. A custom NLP development company trains or fine-tunes models on your data, integrates them with your systems, and gives you control over accuracy, hosting, and running costs.
How much does NLP development cost?
Cost depends on the use case, data volume and quality, number of languages, integration work, and whether you need a pretrained model, fine-tuning, or a model built from scratch. As a guide, a focused NLP solution such as a text classifier or basic chatbot may cost between $10,000 and $30,000, while advanced deep learning or LLM-based systems can range from $50,000 to $75,000 or more. We share a detailed estimate after a short discovery call.
How long does it take to build an NLP solution?
A focused proof of concept usually takes 4 to 6 weeks. Production systems with custom training, integrations, and testing typically take 3 to 6 months, depending on data readiness and scope.
How much training data do we need for an NLP project?
It depends on the task. Pretrained transformer models and LLMs can produce useful results with a few hundred to a few thousand labeled examples, and sometimes fewer with careful prompting. Highly specialized domains need more data. We assess your data during discovery and can handle annotation when labeled data is limited.
Should we use an LLM or a traditional NLP model?
Not every task needs an LLM. Smaller models such as BERT are faster and cheaper for high-volume classification and extraction, while LLMs suit summarization, open-ended questions, and complex reasoning. Many solutions we deliver use both, routing each task to the most cost-effective model.
How do you keep sensitive text data secure?
We work under NDA with role-based access, encryption, and secure development environments, and we can deploy models in your own cloud or on-premise so data stays under your control. Xicom holds ISO/IEC 27001, ISO/IEC 42001, and SOC 2 Type II certifications.
Can you integrate NLP into our existing software?
Yes. We expose NLP capabilities through APIs and connect them with CRMs, help desks, document management systems, and data platforms. Our AI integration team plans the rollout so your current workflows keep running without disruption.
Every award marks a milestone in our journey of excellence
As an AI-first digital engineering company, Xicom has earned global recognition for delivering innovative, scalable, and high-performing technology solutions. Our awards reflect the trust of clients and industry leaders alike.