×
Hire ML Engineers in India
20+Years Exp.
750+Clients
1800+Projects
65%Cost Saved
 ISO 9001 Certified
NASSCOM Member
NDA Protected
48hr Onboarding
Our valued Brands & Agencies







Hire our ML engineers for a range of ML engineering services
Hire our ML engineers for a range of ML engineering services tailored to your technical requirements and business objectives. Our engineers work within your existing technology environment, collaborating with your teams to provide specialized expertise and support machine learning initiatives from engineering through production.

ML Application Engineering
Our ML engineers integrate machine learning capabilities into enterprise applications and workflows. They connect existing models, APIs, data pipelines, and application components to deliver usable ML features. This includes inference workflows, data handling, application integration, and engineering support required to incorporate machine learning into existing products and operational systems.

ML Model Integration
We integrate pre-trained, third-party, and client-provided models with existing technology environments. Our engineers handle model APIs, inference workflows, input and output processing, service integration, and application connectivity. This enables organizations to incorporate machine learning capabilities into their products without rebuilding their existing application architecture.

MLOps Engineering
Our engineers establish and maintain the infrastructure required to operationalize ML workflows. This includes experiment tracking, model versioning, CI/CD pipelines, deployment automation, and environment management. The engineering approach supports reproducible workflows and provides the operational foundation required to move ML capabilities through development and production.

Model Optimization
Our ML engineers optimize existing models to address production requirements such as latency, scalability, resource consumption, and inference efficiency. Depending on the workload, this can involve parameter tuning, quantization, model compression, feature optimization, and inference improvements while maintaining the performance requirements defined for the application across diverse production environments.

Generative AI Engineering
Our ML engineers build applications around existing LLMs and foundation models, including RAG systems, AI assistants, semantic search, document processing, and information extraction. Their work covers retrieval pipelines, prompt workflows, model integration, evaluation, and connections to enterprise data, helping organizations incorporate generative AI into existing products and workflows.

ML Infrastructure and Deployment
We engineer the infrastructure required to deploy and operate ML workloads across cloud and on-premise environments. This includes containerization, inference APIs, GPU infrastructure, deployment pipelines, scaling, and service configuration. Engineers align the infrastructure with application requirements to support reliable, secure, and scalable ML workloads in production environments.
Hire dedicated ML engineers to build, train, and deploy your models
Build scalable, production-ready ML solutions with experienced machine learning engineers who bring hands-on expertise in predictive modeling, data pipelines, model training, and MLOps to turn your data into measurable business outcomes.
| Range of Developers | Junior Developers | Mid-Level Developers | Senior Developers |
|---|---|---|---|
| Hourly Rate | $25/hr | $35/hr | $45/hr |
| Years of Experience | 1–3 Years | 3–5 Years | 5+ Years |
| Project Manager Support | Yes | Yes | Yes |
| Time Zone Flexibility | Available | Available | Available |
| Quality Assurance | Included | Included | Included |
| Working Hours | 40 hours/Week | 40 hours/Week | 40 hours/Week |
Accelerating enterprise transformation through AI and digital engineering.
20+
Years in Business
350+
IT Professionals
ISO 9001 Certified
NASSCOM & STPI Accreditation
NASSCOM & STPI Accreditation
750+
Clients Worldwide
1800+
Projects Executed
Industry-specific ML solutions we build
Hire machine learning engineers from Xicom who combine hands-on ML expertise with practical industry knowledge to build custom solutions for your sector. We build models that solve real business challenges, from demand forecasting and risk scoring to process automation, while opening new opportunities for growth in your industry.
Automotive
Real Estate
Entertainment
Retail & Ecommerce
Healthcare
Transportation
Manufacturing
Travel & Tourism
Professional Services
Software Vendors
Banking & Finance
Education
Predictive Modeling
Our ML engineers build predictive systems that use historical and current data to estimate future outcomes. Their expertise covers selecting relevant variables, preparing training data, identifying suitable modeling approaches, and interpreting predictions for business applications such as demand forecasting, risk assessment, customer behavior analysis, and operational planning.
Statistical Modeling
Statistical modeling helps quantify relationships within data and understand the factors influencing an outcome. Our ML engineers work with regression, probability-based methods, hypothesis testing, and statistical inference to analyze patterns, estimate outcomes, and establish reliable relationships between variables for analytical and predictive applications.
Feature Engineering
The quality of model inputs can significantly affect predictive performance. Our ML engineers transform raw data into meaningful features through aggregation, encoding, normalization, selection, and other preparation techniques. They also identify relevant variables and refine feature sets to provide models with useful information while controlling unnecessary complexity.
Model Training
Our ML engineers handle the engineering processes required to train machine learning models using prepared datasets. This includes configuring training workflows, selecting appropriate parameters, managing experiments, handling training data, and addressing issues that arise during training. The objective is to produce models that perform consistently against defined requirements.
Model Evaluation
Evaluating a model involves more than checking a single accuracy figure. Our ML engineers assess models using metrics appropriate to the problem, examine errors and prediction behavior, validate performance on unseen data, and compare results against defined benchmarks. This helps establish whether a model is suitable for its intended application.
Model Optimization
Our ML engineers optimize existing models when production requirements demand improvements in performance, latency, resource usage, or scalability. Depending on the workload, optimization may involve parameter tuning, feature refinement, model compression, quantization, or inference improvements. The approach is selected according to the model architecture, requirements, and infrastructure.
Deep Learning
Our ML engineers work with deep learning architectures for problems requiring more complex pattern recognition and representation learning. Their expertise includes neural network configuration, training workflows, performance evaluation, and optimization. Deep learning can support applications involving large datasets, high-dimensional inputs, and problems where conventional ML approaches are insufficient.
Time-Series Modeling
Time-series modeling addresses data where observations are recorded sequentially over time. Our ML engineers analyze trends, seasonality, temporal dependencies, and changing patterns to support forecasting and planning applications. Their work can help organizations estimate future demand, identify emerging changes, and incorporate historical time-dependent behavior into predictive systems.
Recommendation Systems
Recommendation systems use behavioral, transactional, contextual, and other relevant data to identify items or actions that may be appropriate for a particular user or situation. Our ML engineers work with recommendation approaches, ranking methods, feature design, and evaluation processes to support personalized experiences across digital products and services.
Anomaly Detection
Our ML engineers apply anomaly detection techniques to identify observations or behaviors that differ significantly from established patterns. Depending on the data and use case, this can involve statistical methods, distance-based approaches, clustering, or machine learning models. Applications include detecting unusual transactions, operational events, system behavior, and other deviations requiring investigation.
Case Studies: machine learning projects we've delivered
See how our ML engineers have helped clients across industries build machine learning solutions that sharpen forecasting, automate decisions, reduce operational costs, and turn business data into lasting value.
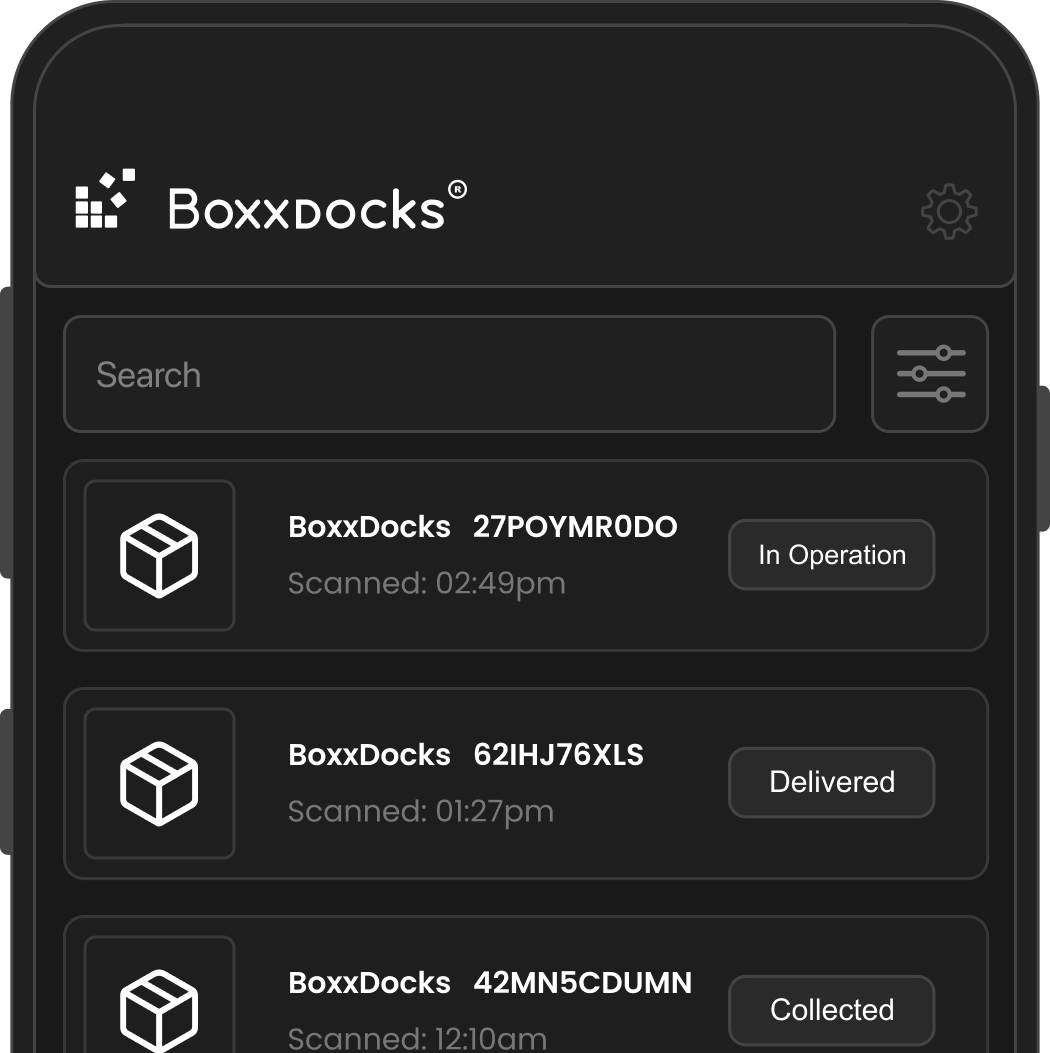
BoxxDocks AI Asset Tracking Platform
The Challenge
Asset tracking was manual, error-prone, and scattered across disconnected systems. The client had no centralized visibility into asset movement, no real-time location data, and no way to generate instant reports across multiple enterprise clients from a single platform.
Our Approach
We built BoxxDocks as an AI-enabled asset lifecycle platform using QR/NFC scanning, real-time dashboards, geolocation tracking, and a RAG-powered conversational engine that lets users query live operational data in plain English instead of navigating dashboards.
The Result
- Real-time inventory tracking across warehouses, transit, and delivery
- AI query engine for natural language insights
- LLM-powered reporting with anomaly detection
- Complete audit trail with location, timestamp, and status
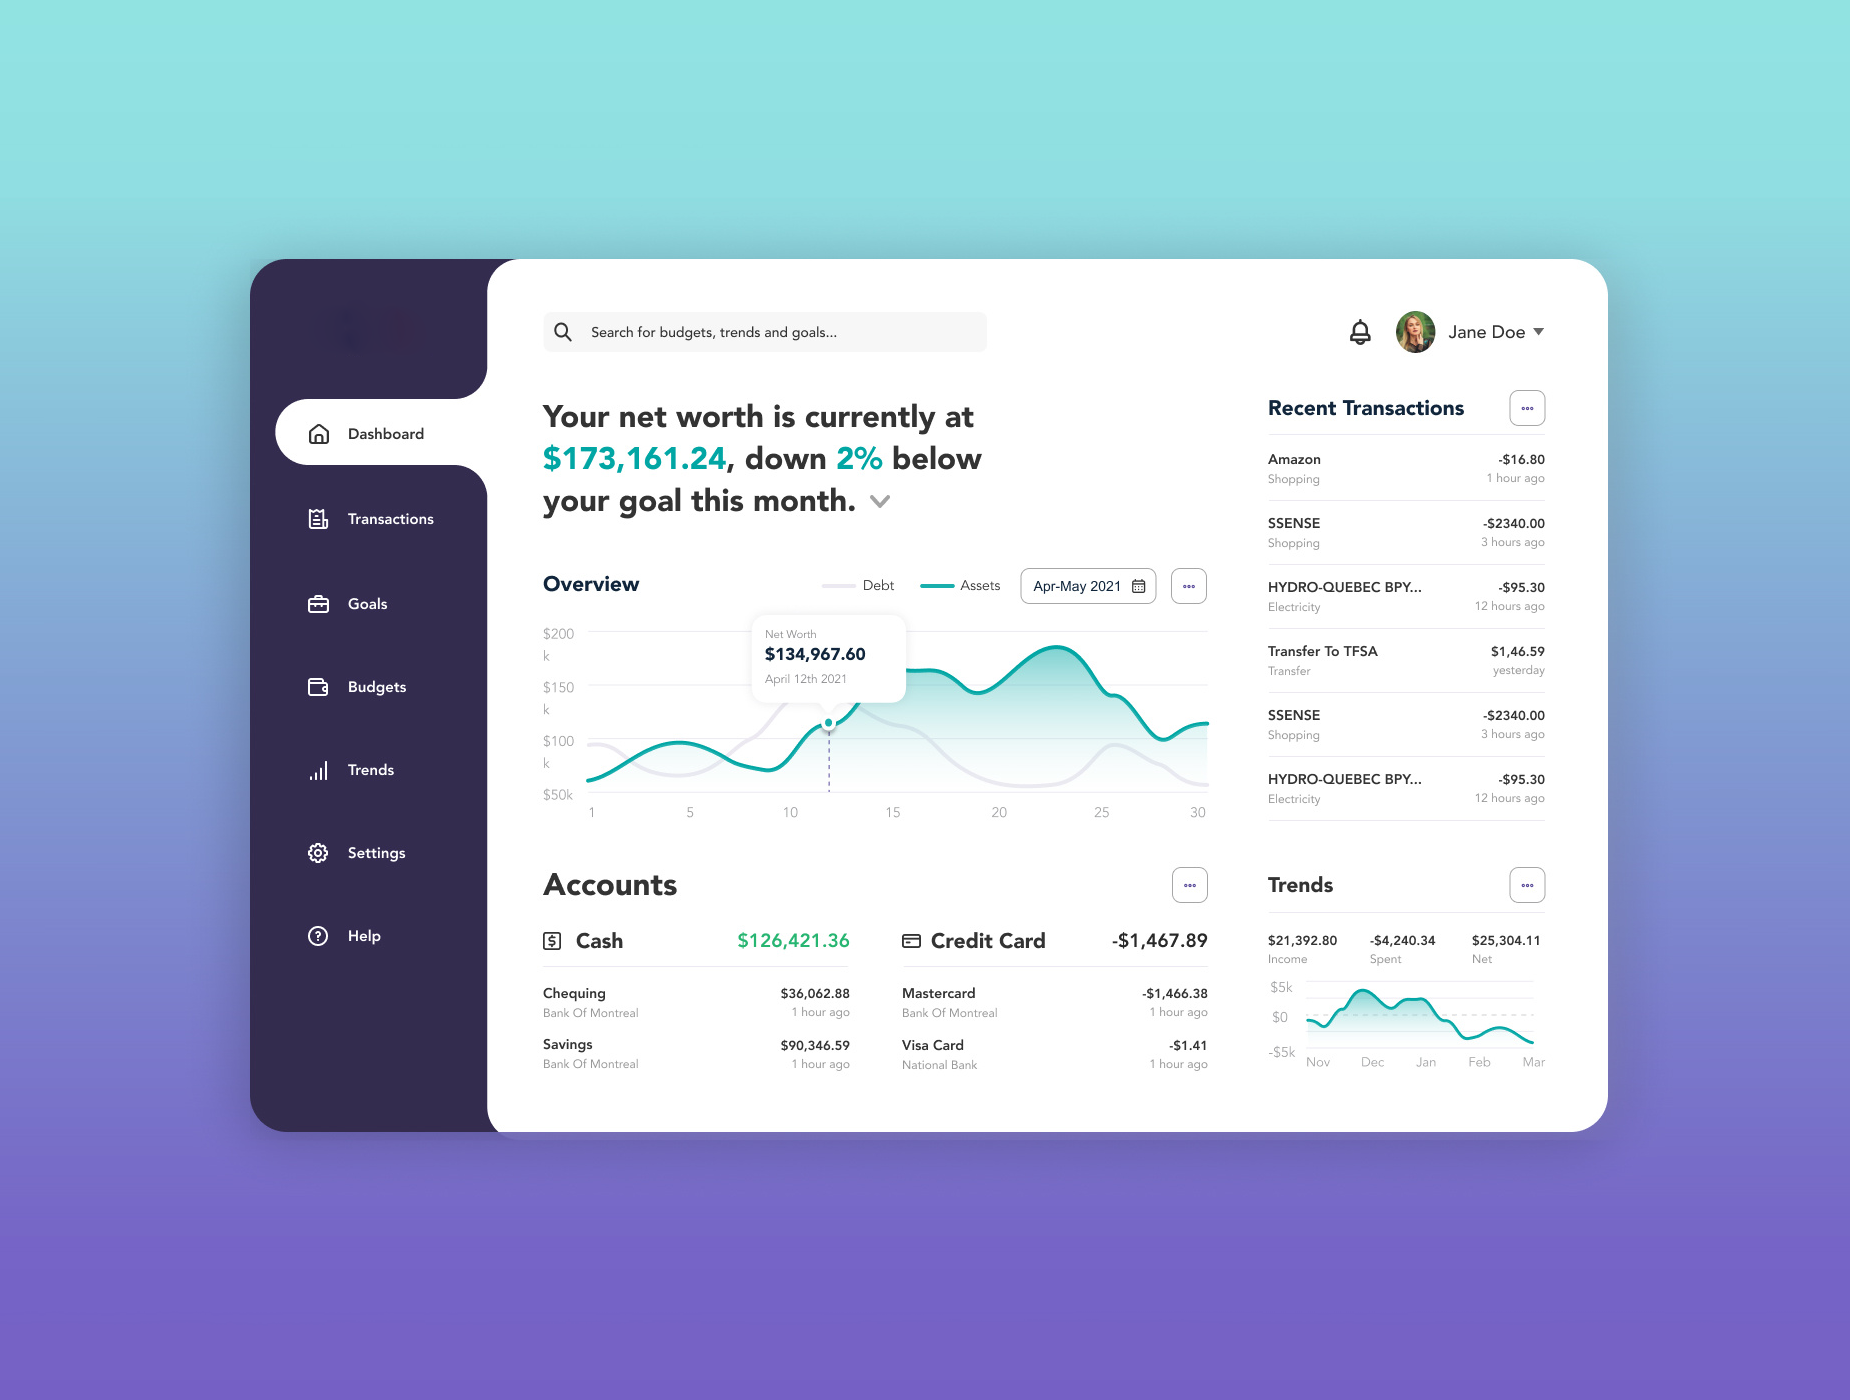
Parity AI AI Finance Platform
The Challenge
Personalized financial advice was expensive and limited to periodic meetings. Users had no way to consolidate banking, investments, debt, and insurance into one platform with real-time, AI-driven guidance.
Our Approach
We built Parity AI as an always-on financial wellness platform powered by AI. It securely pulls data from multiple sources, analyzes user behavior, forecasts outcomes, and delivers personalized recommendations — acting as a digital financial advisor, not a budgeting app.
The Result
- AI-powered financial planning across banking, investments, and debt
- Personalized recommendations based on life events and behavior
- Integrated financial education with actionable insights
IELTS AI-Powered Speaking Evaluator
The Challenge
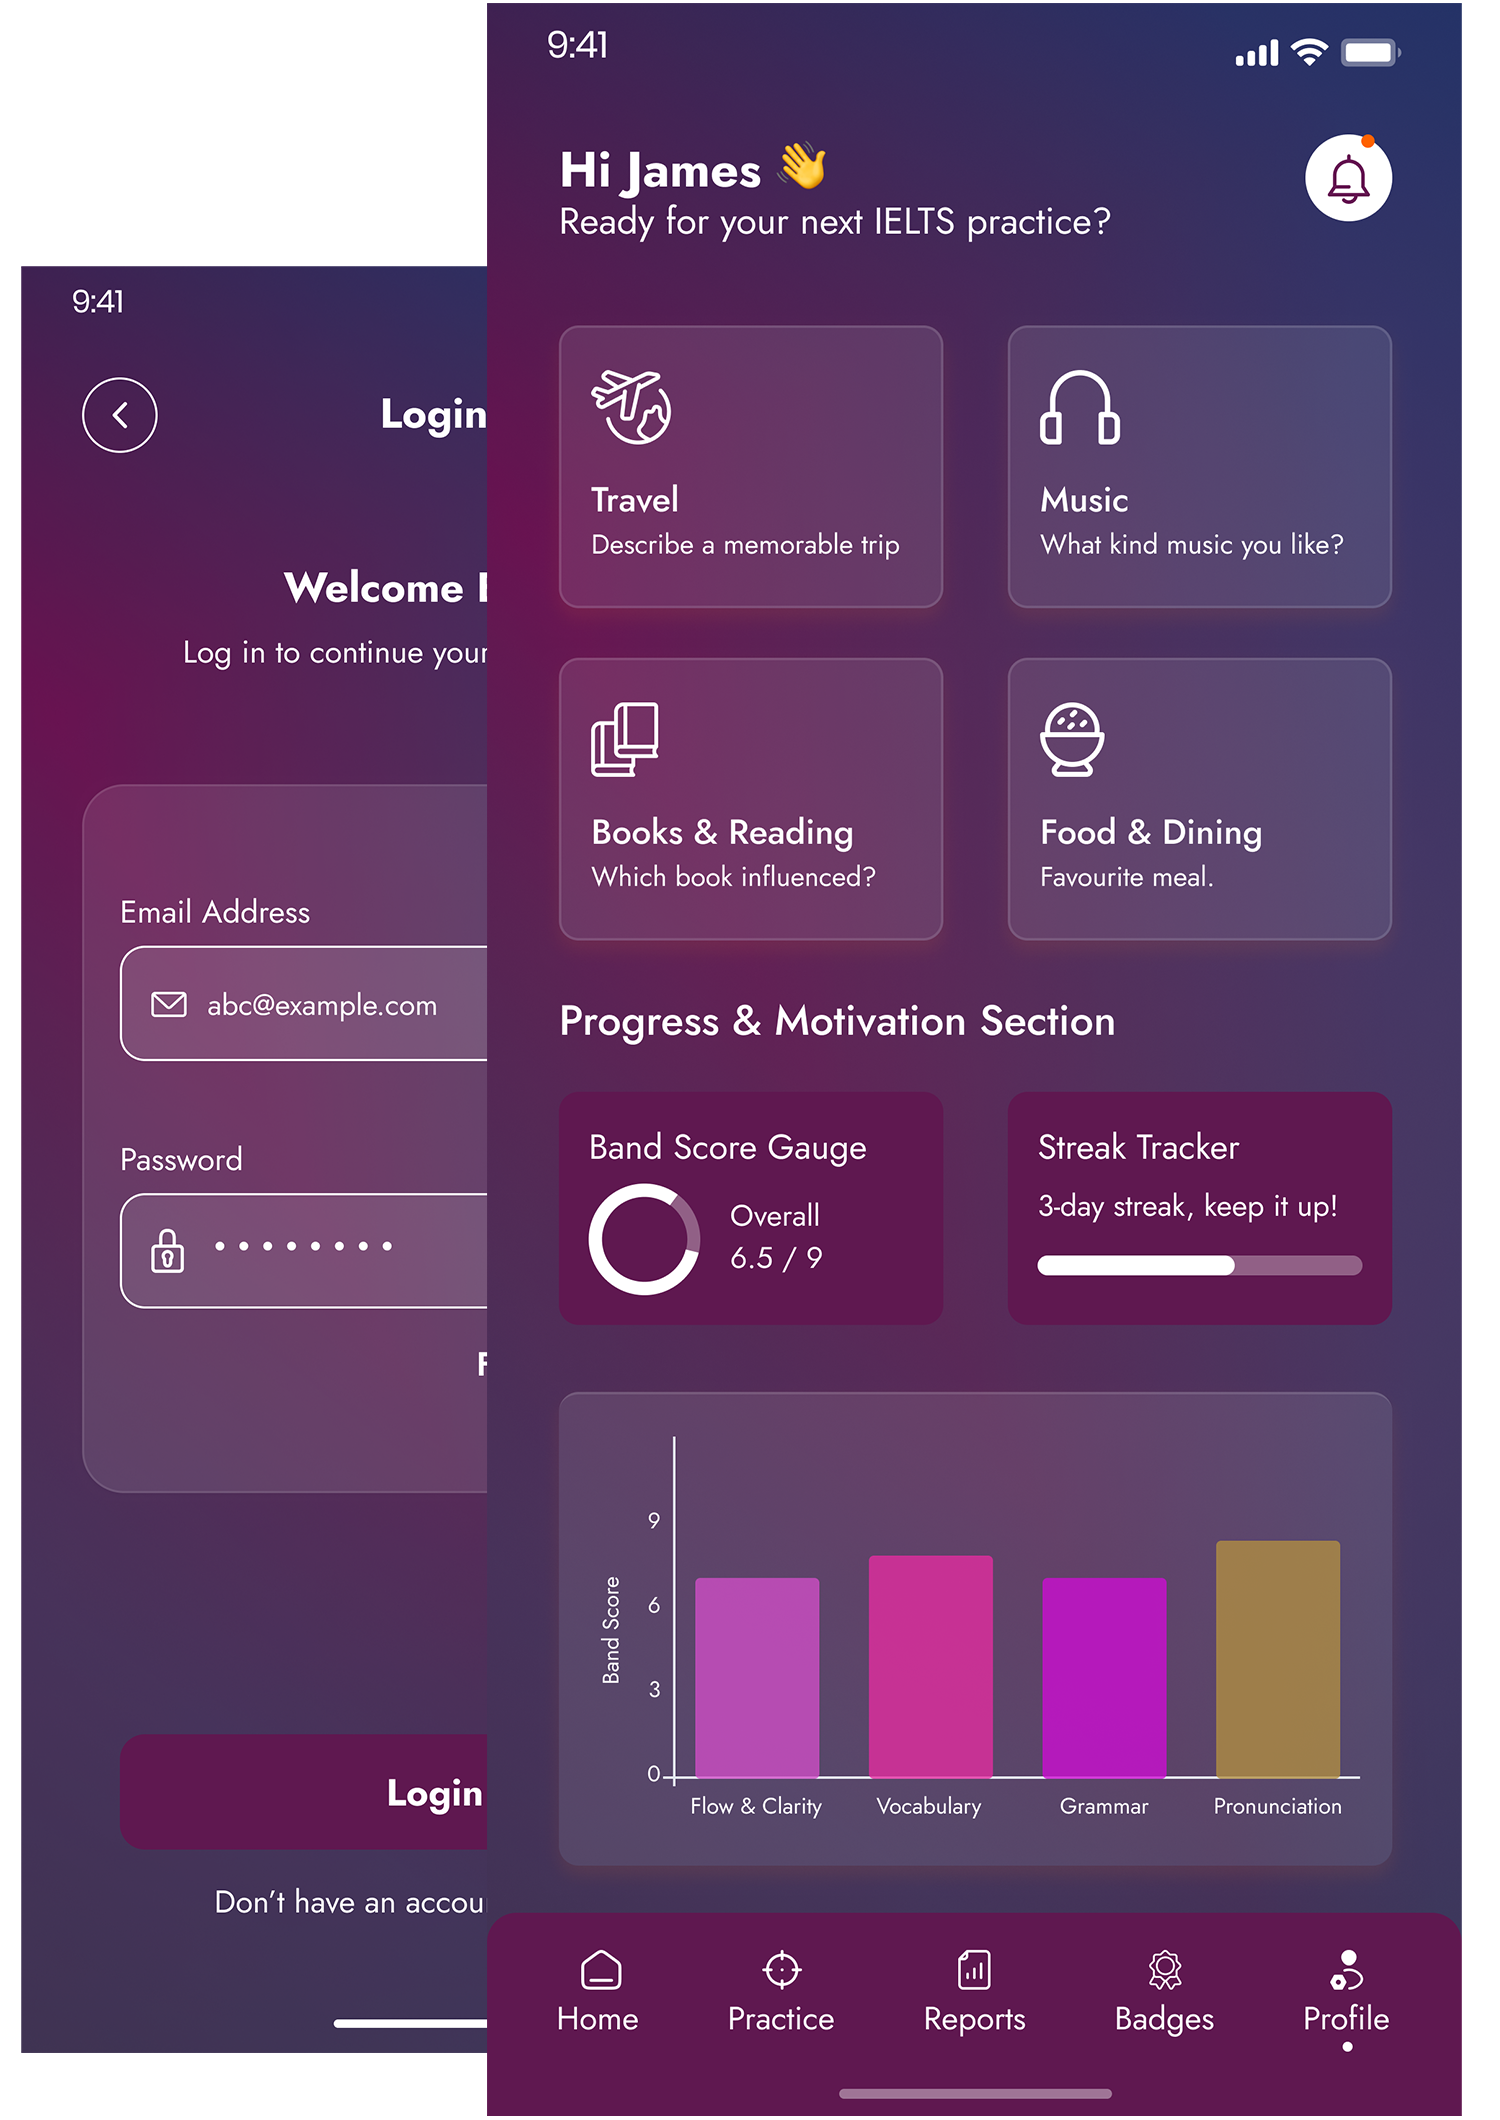
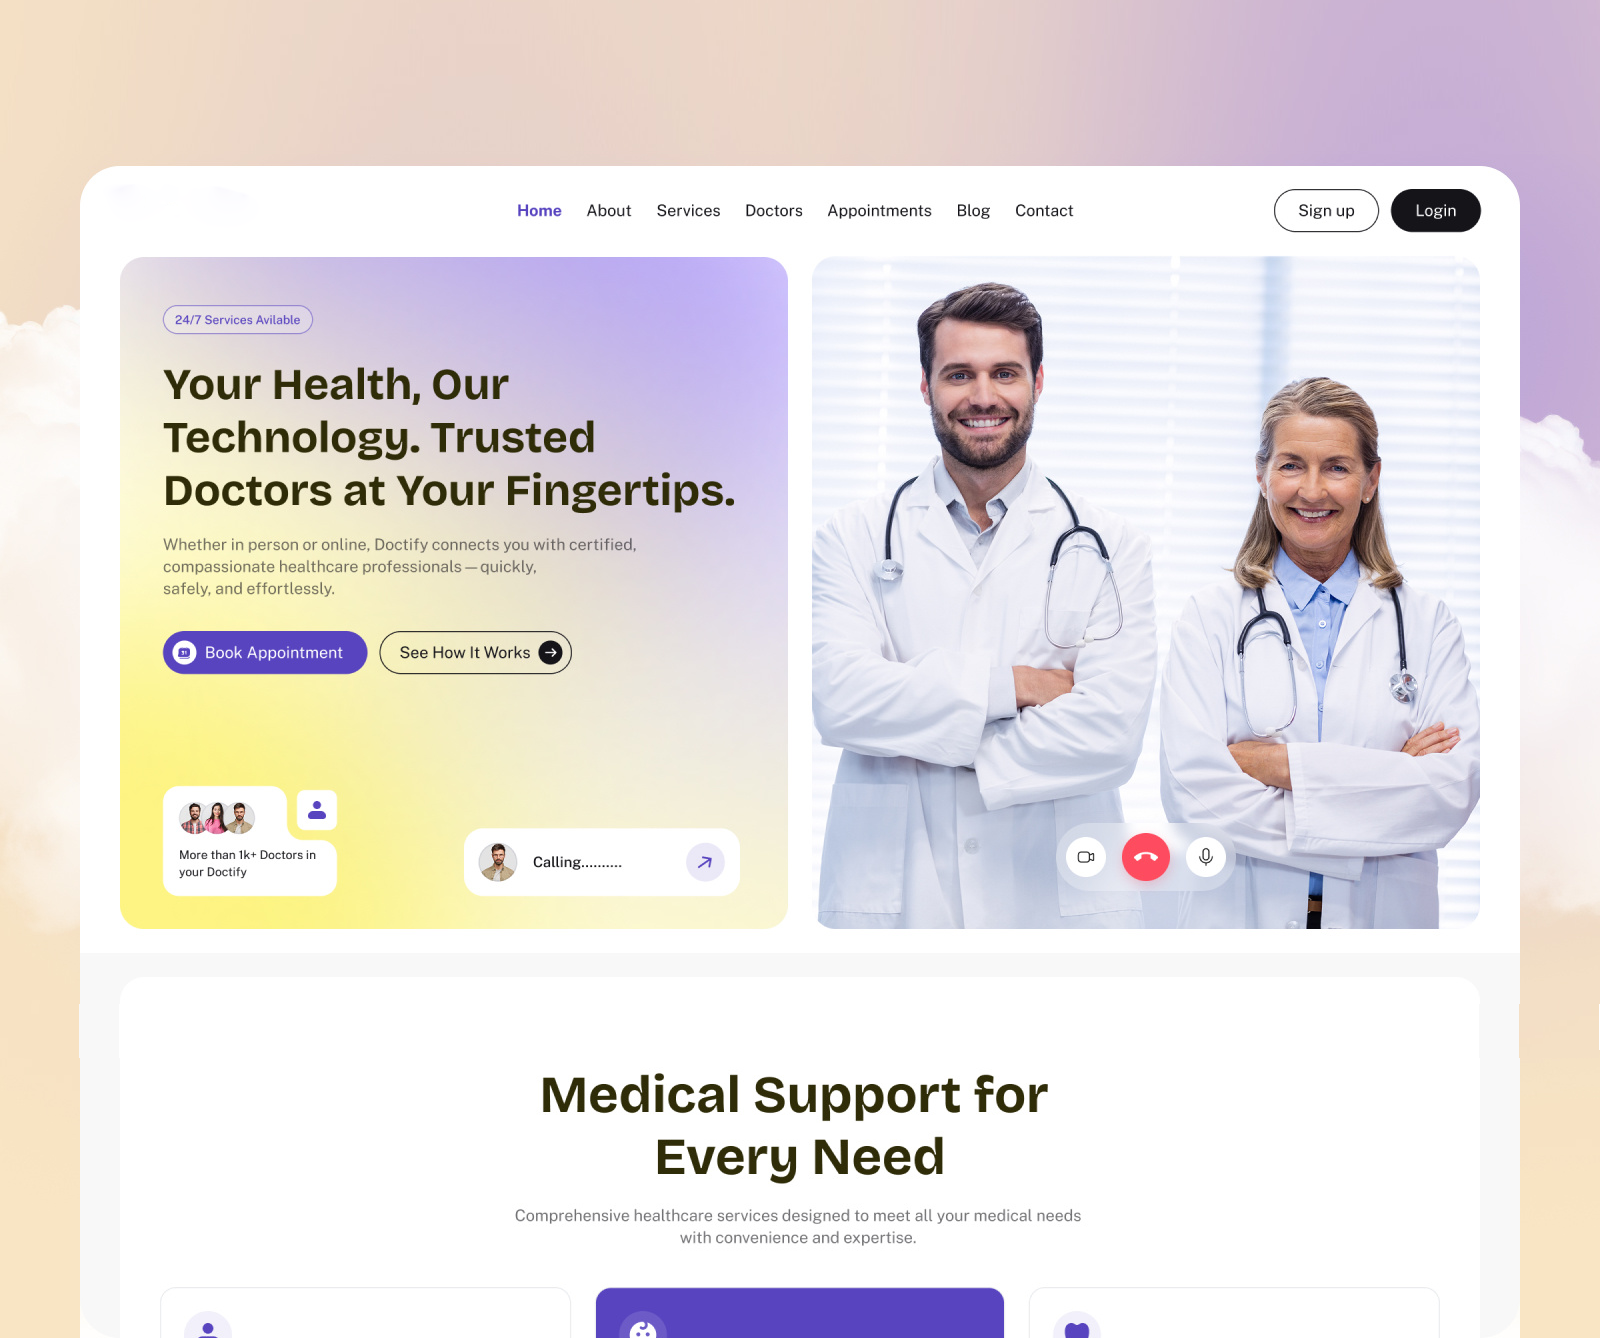
Human IELTS tutors cost $30-$80/hour with limited availability. Generic speaking apps lack authentic Part 1/2/3 exam structure, pronunciation feedback, and band-aligned scoring rubrics. Learners had no way to get unlimited, exam-authentic practice at scale.
Our Approach
We built a full-stack AI platform with a lifelike AI Avatar Examiner using LangGraph + Gemini conversation engine, Google Cloud TTS with viseme lip-sync, Faster-Whisper ASR, and a 6-layer IELTS evaluation pipeline scoring all 4 criteria with ±0.5-1.0 band accuracy.
The Result
- 1,000+ concurrent users with 2–3s response latency
- 10x lower cost than human examiners
- 6-service AI microservice with model preloading
- No-code admin panel for rapid content updates
Health E Livin AI Wellness Platform
The Challenge
People struggling with mental health had no single platform to access trusted information, take confidential assessments, and find providers — all without stigma or privacy concerns.
Our Approach
We built HealtheLivin as an AI-powered mental wellness app with a conversational AI assistant, anonymous screenings, evidence-based resource library, and geolocation-based provider discovery — all on privacy-first cloud infrastructure.
The Result
- AI knowledgebase for natural language mental health support
- Confidential assessments with personalized wellness insights
- Location-based provider discovery for professional care
- Privacy-first architecture with encrypted data management
Today Fit Fitness App
The Challenge
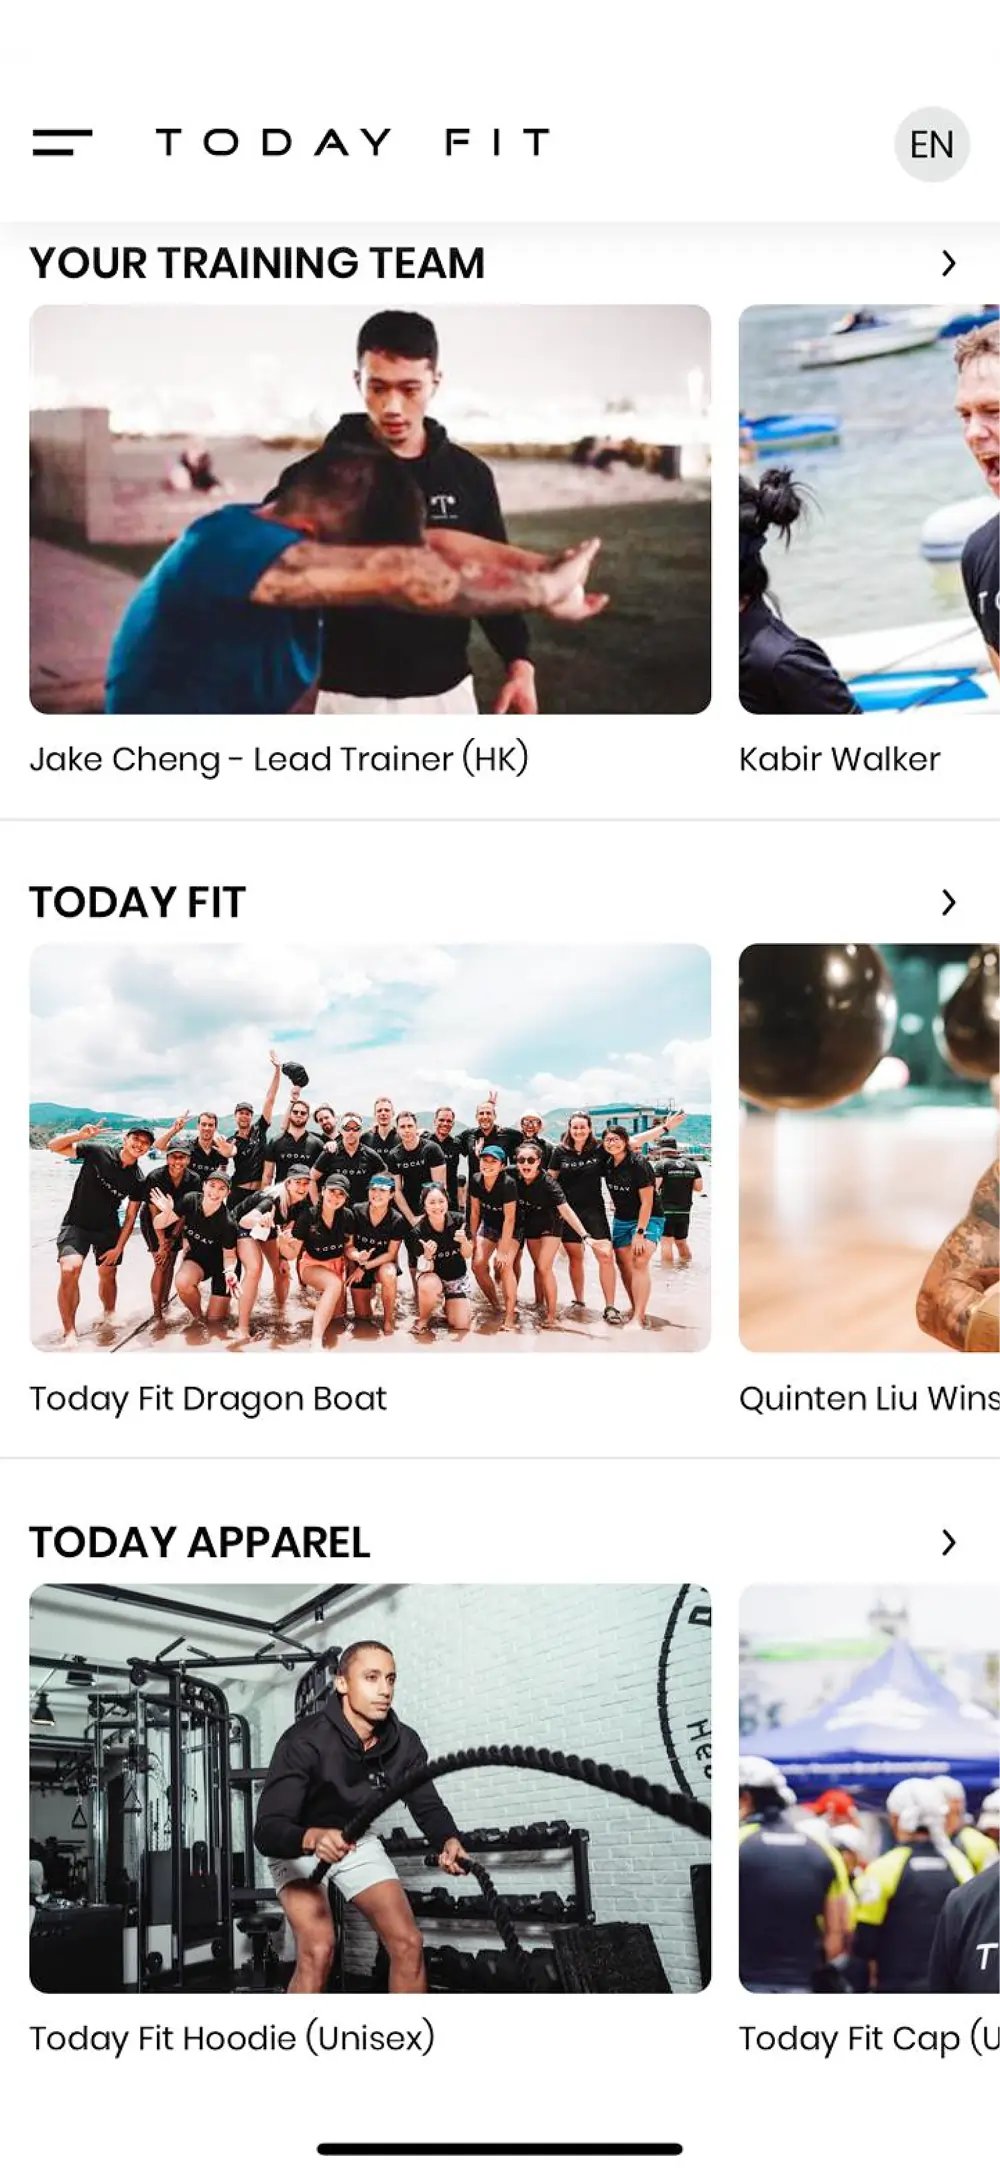
Gyms, trainers, and users were stuck with disconnected tools for scheduling, payments, and fitness tracking. There was no single platform that combined personalized fitness with business management.
Our Approach
We developed TodayFit as an AI-driven fitness platform with trainer booking, personalized tracking, community features, and a SaaS layer for gym and trainer business management.
The Result
- 30% increase in user engagement
- 4.7+ average rating on the App Store and Play Store
- 60% growth in trainer bookings
- 45% increase in subscription conversions
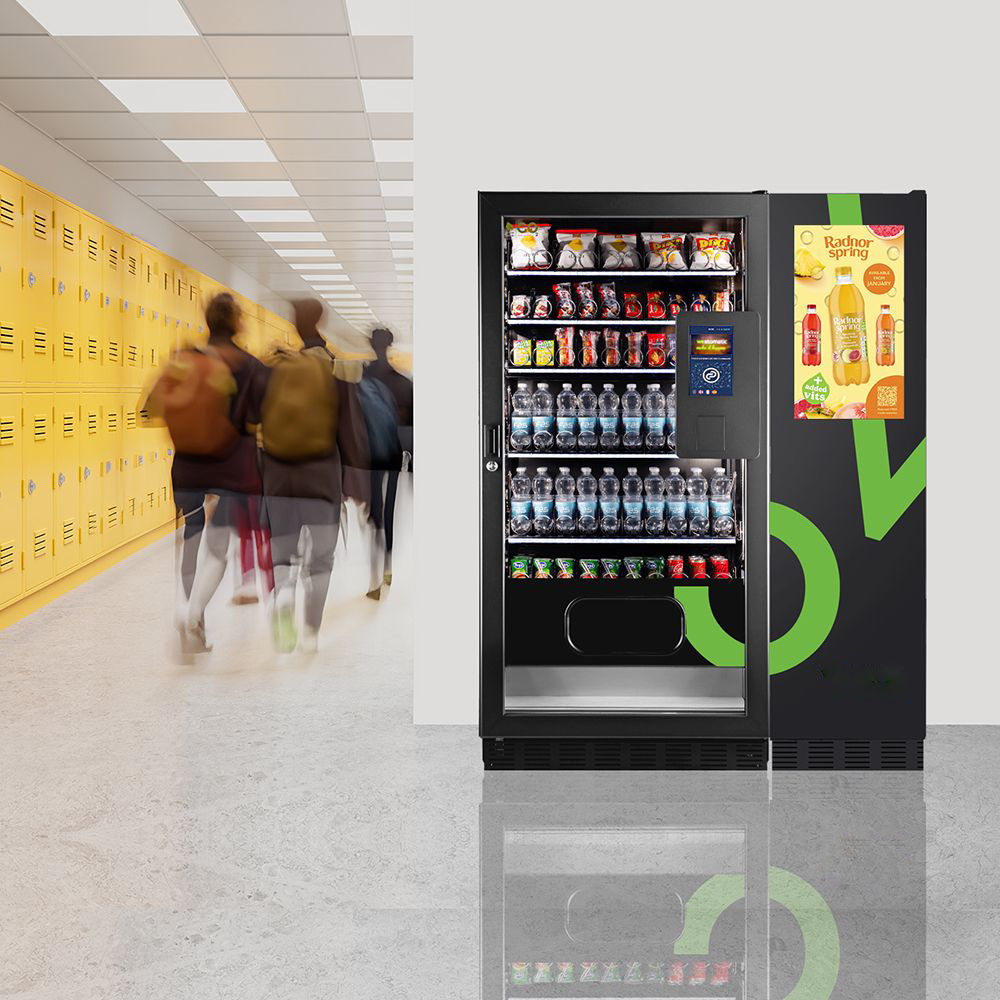
SmartVend AI Smart Vending Platform
The Challenge
Managing a distributed vending machine network meant manual inventory tracking, disconnected payment systems, no remote management capability, and zero real-time visibility into machine health or sales performance across locations.
Our Approach
We built SmartVend as a cloud-connected IoT platform combining an Android kiosk app, centralized web portal, real-time inventory sync, hardware integration for payments and dispensing, and a digital advertising layer — all managed from a single dashboard.
The Result
- Real-time inventory sync with low-stock alerts
- Remote machine management across unlimited locations
- IoT integration for payments, dispensing, and monitoring
- Centralized sales analytics and revenue reporting
Build your ML team
Hire dedicated machine learning engineers to design, train, and deploy models that turn your business data into accurate predictions and smarter decisions.
Tech stack our machine learning engineers use to build intelligent solutions
Hire machine learning engineers who work with modern ML frameworks, cloud ML platforms, and MLOps tooling to build, deploy, and monitor models that stay accurate, scalable, and reliable in production.
 Python
 PyTorch
 TensorFlow
 JAX
 Keras
 Scikit-learn
 SageMaker
 Azure ML
 Vertex AI
 Databricks
 Snowflake
 MongoDB
 PostgreSQL
 Pandas
 NumPy
 Spark
 Kafka
 Airflow
 dbt
 MLflow
 Kubeflow
 DVC
 Docker
 Kubernetes
 BentoML
 Evidently AI
 Arize AI
 Fiddler AI
 Prometheus
 Grafana

Existing ML Systems
Our engineers can work with existing machine learning systems to extend capabilities, improve performance, troubleshoot technical issues, and support ongoing maintenance. They can understand established workflows, interfaces, and dependencies before making changes, helping organizations enhance their current ML environment without unnecessarily replacing components or disrupting operational systems.

APIs and Services
ML capabilities often need to connect with applications through APIs and backend services. Our engineers can work across these interfaces, handling data exchange, inference requests, service integration, and application connectivity. They can also contribute to microservice-based architectures where machine learning functionality operates as part of broader software systems.

Data Pipelines
Our ML engineers can work with established data pipelines that support machine learning workloads, including ingestion, transformation, processing, validation, and feature preparation. They can collaborate with data engineering teams to understand pipeline dependencies, address integration requirements, and ensure ML applications receive the data needed within existing processing workflows.

Cloud Infrastructure
Our engineers can work within existing cloud environments supporting ML workloads, including compute resources, storage, containers, and deployment infrastructure. They can adapt to the organization's cloud architecture and engineering practices while contributing to infrastructure configuration, deployment workflows, resource optimization, and operational requirements for ML workloads.

Enterprise Applications
Machine learning capabilities often need to operate within established business applications rather than separately. Our engineers can integrate ML functionality with enterprise software, operational platforms, and internal systems, working with existing application architectures, interfaces, workflows, and dependencies to support the practical use of machine learning across business processes.

Development Teams
Our ML engineers can join established development teams and collaborate with software engineers, data scientists, architects, DevOps engineers, and product teams. They can follow existing coding standards, repositories, project workflows, communication practices, and delivery processes, allowing them to contribute as part of the broader engineering team rather than operating separately.
Our ML engineer hiring process: From requirements to deployment
Our ML engineer hiring process is structured to understand your requirements, identify suitable engineering expertise, establish the right engagement, and integrate engineers into your team. We maintain clear communication throughout to support efficient onboarding, collaboration, delivery, and evolving project requirements.
1
Requirements
We discuss your project goals, technical requirements, existing environment, team structure, timelines, and specific ML engineering expertise needed for your initiative.
2
Selection
We identify ML engineers whose technical expertise, experience, project exposure, and engineering capabilities align with your requirements and working environment.
3
Engagement
We establish responsibilities, engagement structure, timelines, deliverables, and collaboration expectations before the selected ML engineers begin contributing.
4
Onboarding
Our engineers become familiar with your architecture, codebase, workflows, development practices, tools, and project requirements to begin contributing effectively.
5
Delivery
Engineers contribute to agreed requirements while we adjust responsibilities, capacity, or team composition as your ML engineering needs evolve.
Engagement models for hiring our ML engineers
Choose an engagement structure based on your project scope, internal team capacity, and the level of ML engineering support required. Our engineers can contribute to a specific initiative, extend an existing team, or provide dedicated engineering capacity for ongoing machine learning requirements.
Hire dedicated ML engineers who work exclusively on your projects throughout the engagement. They become an extension of your engineering team, collaborate with internal stakeholders, follow your established development practices, and contribute continuously to ML initiatives. This model provides consistent engineering capacity for ongoing requirements, evolving priorities, and long-term projects.
Add ML engineers to your existing development, data science, or engineering team when additional expertise or capacity is required. They work alongside your in-house resources, contribute to defined responsibilities, and follow your existing architecture, repositories, workflows, and delivery practices. This model supports targeted team expansion without changing your established project structure.
Bring in ML engineering expertise for a defined project, initiative, or technical requirement with a specific scope and timeframe. Our engineers contribute to the agreed deliverables while working within your existing technical environment and processes. This model suits organizations that need specialized ML engineering capabilities without maintaining additional resources after project completion.
Client testimonials and reviews showcasing the value we consistently deliver
Explore how our clients describe their journey with us, reflecting strong collaboration, effective execution, and consistent outcomes delivered across engagements. See how our delivery framework ensures consistency from initiation through to successful completion.
❝
Parity AI
We came to Xicom with an ambitious goal: make institutional-grade financial planning accessible to everyone through AI. Xicom went beyond the brief, blending conversational AI and predictive analytics into an effortless platform. Parity AI is exactly what we envisioned.
❝
RadioFX
Xicom took the time to understand what our stations and listeners actually need, building something tailored rather than generic. Live chat and polls are now core to how we connect with our audience — the app has become a true extension of our on-air presence.
❝
StudyBuddy
Xicom built exactly what our students needed: a secure space to connect, collaborate, and find tutoring support in one place. Their understanding of student behavior shows in how naturally everything fits together — StudyBuddy is something students genuinely rely on.
❝
BoxxDocks
Xicom helped us bring BoxxDocks to life exactly as we envisioned it. Their team understood the complexity of AI powered real-time asset tracking and delivered a platform that's both powerful and genuinely easy to use.
❝
TodayFit
We are very happy with their services. I cannot recommend them highly enough. The value, ability, and delivery that we have seen has been superb, and we look forward to continuing this relationship.
❝
SmartVend AI
Their team built SmartVend from the ground up, combining hardware integration, real-time inventory sync, and a centralized dashboard that completely changed how we operate. We couldn't have asked for a more capable technical partner.
❝
Tap Retail
Partnering with Xicom to develop our Tap Retail app and website was one of the best decisions we made. Their team demonstrated exceptional professionalism, technical expertise, and a deep understanding of our business goals.
❝
GoGmGo
Partnering with Xicom was a game-changer for us. They didn't just build software, they helped us redefine how we run our business. Their proactive support and deep domain knowledge gave us the confidence to innovate faster.
❝
DENVEN
Working with Xicom has been a transformative experience. Their team quickly understood our challenges and delivered a scalable, intuitive solution. I highly recommend Xicom to any organization seeking future-ready, high-performance digital products.
Top tech insights of our blog
Explore latest tech stories & News
✦ AI-First Company
Deep Insights into Emerging Technology and Innovation!
Stay ahead in the digital world with our latest insights covering AI trends, industry developments, and expert advice on building smarter businesses.
1800+
Projects
20+
Years Experience
Frequently Asked Questions
What does a machine learning engineer do?
A machine learning engineer designs, trains, and deploys models that learn from data to make predictions or automate decisions. At Xicom, our ML engineers handle the full lifecycle, from data preparation and feature engineering to model training, deployment, and ongoing monitoring in production.
What hiring models do you offer for ML engineers?
You can hire ML engineers on a dedicated full-time basis, a part-time basis, or an hourly model. Each option lets you scale your team up or down as project needs change, and you keep direct communication with the engineers working on your project.
How quickly can I hire machine learning engineers from Xicom?
Once we understand your requirements, we share shortlisted ML engineer profiles that match your tech stack and domain. You can interview candidates directly, and onboarding starts as soon as you finalize your selection. Exact timelines depend on the skills and seniority you need.
How much does it cost to hire a machine learning engineer?
The cost to hire an ML engineer depends on experience level, project complexity, engagement model, and required skills such as deep learning, NLP, or MLOps. Share your requirements with us and we will provide a transparent quote based on your scope.
What is the difference between a machine learning engineer and a data scientist?
A data scientist focuses on analyzing data, testing hypotheses, and building experimental models. A machine learning engineer takes those models and makes them production-ready by building scalable pipelines, deploying models, and monitoring their performance. Many projects need both, and Xicom can support either role.
What types of ML solutions can your engineers build?
Our ML engineers build predictive analytics models, recommendation engines, fraud detection systems, demand forecasting tools, computer vision applications, NLP solutions, and anomaly detection systems. Each solution is tailored to your data, industry requirements, and business goals.
Do you provide support after an ML model is deployed?
Yes. ML models can lose accuracy over time as real-world data changes. Our engineers monitor model performance, detect data drift, retrain models when needed, and maintain deployment pipelines so your ML solutions stay accurate and reliable.
Every award marks a milestone in our journey of excellence
As AI-first digital engineering company, Xicom has earned global recognition for delivering innovative, scalable, and high-performing technology solutions. Our awards reflect the trust of clients and industry leaders alike.