×
Hire Generative AI Developers in India
20+Years Exp.
750+Clients
1800+Projects
65%Cost Saved
 ISO 9001 Certified
NASSCOM Member
NDA Protected
48hr Onboarding
Our valued Brands & Agencies







Services our generative AI developers offer
Our generative AI development services cover the full delivery lifecycle, from solution design and model integration to fine-tuning, deployment, and long-term support, so your AI systems stay accurate and aligned with changing business needs.
GenAI Consulting & Strategy
We help you identify the right use cases, assess feasibility, and shape a clear implementation roadmap, so generative AI adoption starts on a practical, well-informed foundation.
Custom GenAI Development
We build custom generative AI systems around your workflows, data, and environment, with reliable performance, clean integration with existing tools, and room to scale across teams.
Conversational AI Development
We build conversational AI that handles real customer and employee conversations across web, mobile, and messaging channels, going beyond scripted replies to resolve requests quickly.
Enterprise Search & Knowledge Systems
We build AI-powered search and knowledge systems that surface relevant information from across your organization, breaking down silos and helping teams make better-informed decisions.
Document Intelligence Solutions
We extract and structure data from contracts, invoices, forms, and reports at volume, cutting manual review time and improving processing accuracy.
Multimodal AI Development
We develop multimodal AI solutions that understand and generate text, images, audio, and documents, supporting richer enterprise use cases than text-only models allow.
LLM Integration & Customization
We integrate and customize LLMs inside your existing applications and workflows, with prompts, guardrails, and evaluations tuned to your specific operational needs.
Model Fine-tuning & Optimization
We fine-tune and optimize models to improve accuracy, reduce latency and cost, and align outputs with your industry's terminology and standards.
Generative AI Integration & Deployment
We take your generative AI solution from prototype to production, deploying it securely inside your existing cloud or on-premise infrastructure with monitoring in place from day one.
Maintenance & Support
We monitor, optimize, and update your generative AI solutions after launch, keeping them accurate, secure, and aligned with changing business requirements and newer model releases.
Hire generative AI engineers based on your project needs
Choose junior, mid-level, or senior generative AI developers with hands-on experience in LLM fine-tuning, RAG pipelines, and multimodal AI, matched to your project complexity and budget.
| Range of Developers | Junior Developers | Mid-Level Developers | Senior Developers |
|---|---|---|---|
| Hourly Rate | $25/hr | $35/hr | $45/hr |
| Years of Experience | 1–3 Years | 3–5 Years | 5+ Years |
| Project Manager Support | Yes | Yes | Yes |
| Time Zone Flexibility | Available | Available | Available |
| Quality Assurance | Included | Included | Included |
| Working Hours | 40 hours/Week | 40 hours/Week | 40 hours/Week |
Accelerating enterprise transformation through AI and digital engineering.
20+
Years in Business
350+
IT Professionals
ISO 9001 Certified
NASSCOM & STPI Accreditation
NASSCOM & STPI Accreditation
750+
Clients Worldwide
1800+
Projects Executed
Industries
Our generative AI developers build production-ready AI solutions for a wide range of industries, combining LLM integration, RAG architecture, and multimodal AI to deliver secure, scalable applications that automate workflows and support measurable business growth.
Automotive
Real Estate
Entertainment
Retail & Ecommerce
Healthcare
Transportation
Manufacturing
Travel & Tourism
Professional Services
Software Vendors
Banking & Finance
Education
Prompt Engineering
We design, structure, and iteratively refine prompts to improve model output quality, reduce hallucinations, and align responses with business intent by applying chain-of-thought, few-shot, and structured output techniques across diverse enterprise use cases.
Vector Database Management
We design and manage vector stores using Pinecone, Weaviate, Qdrant, and pgvector, handling embedding generation, indexing strategies, metadata filtering, and retrieval optimization to keep semantic search fast and contextually precise at scale.
Multimodal AI Development
We build systems that process and generate content across text, images, audio, and documents using multimodal foundation models, enabling richer enterprise use cases that go beyond single-modality inputs and outputs in real-world deployments.
Guardrails Engineering
We implement structured evaluation frameworks, output validation, content filtering, and safety guardrails, ensuring AI systems behave predictably, stay within defined boundaries, and meet quality and compliance standards across production environments.
AI Infrastructure & MLOps
We design scalable AI infrastructure for model serving, versioning, monitoring, and cost management using cloud-native tooling and open-source MLOps stacks to keep generative AI systems reliable, observable, and efficient in production.
Synthetic Data Pipelines
We build synthetic data pipelines and structured training datasets that help organizations improve model performance, address data scarcity, and stay privacy compliant without relying on sensitive or limited real-world data.
AI Governance & Compliance
We help organizations establish responsible AI frameworks covering bias assessment, explainability, audit trails, and policy compliance, ensuring generative AI systems operate transparently, ethically, and in line with evolving regulatory requirements.
Memory & Context Management
We architect long-context and memory strategies for AI systems, managing conversation history, session state, and knowledge persistence across interactions to keep responses coherent, relevant, and accurate over extended enterprise workflows.
Data Preprocessing & Chunking
We design and implement data preprocessing and chunking strategies that prepare enterprise content for AI consumption, improving retrieval quality, reducing noise, and ensuring language models receive well-structured, contextually meaningful input.
AI Security & Privacy
We implement security best practices across AI systems, covering data anonymization, access controls, secure model serving, and compliance with privacy regulations, ensuring enterprise AI deployments handle sensitive information responsibly and safely.
Case studies: generative AI projects we've delivered
See how we've partnered with clients across industries to build LLM, RAG, and conversational AI solutions that improve efficiency, enhance customer experiences, cut costs, and create long-term value.
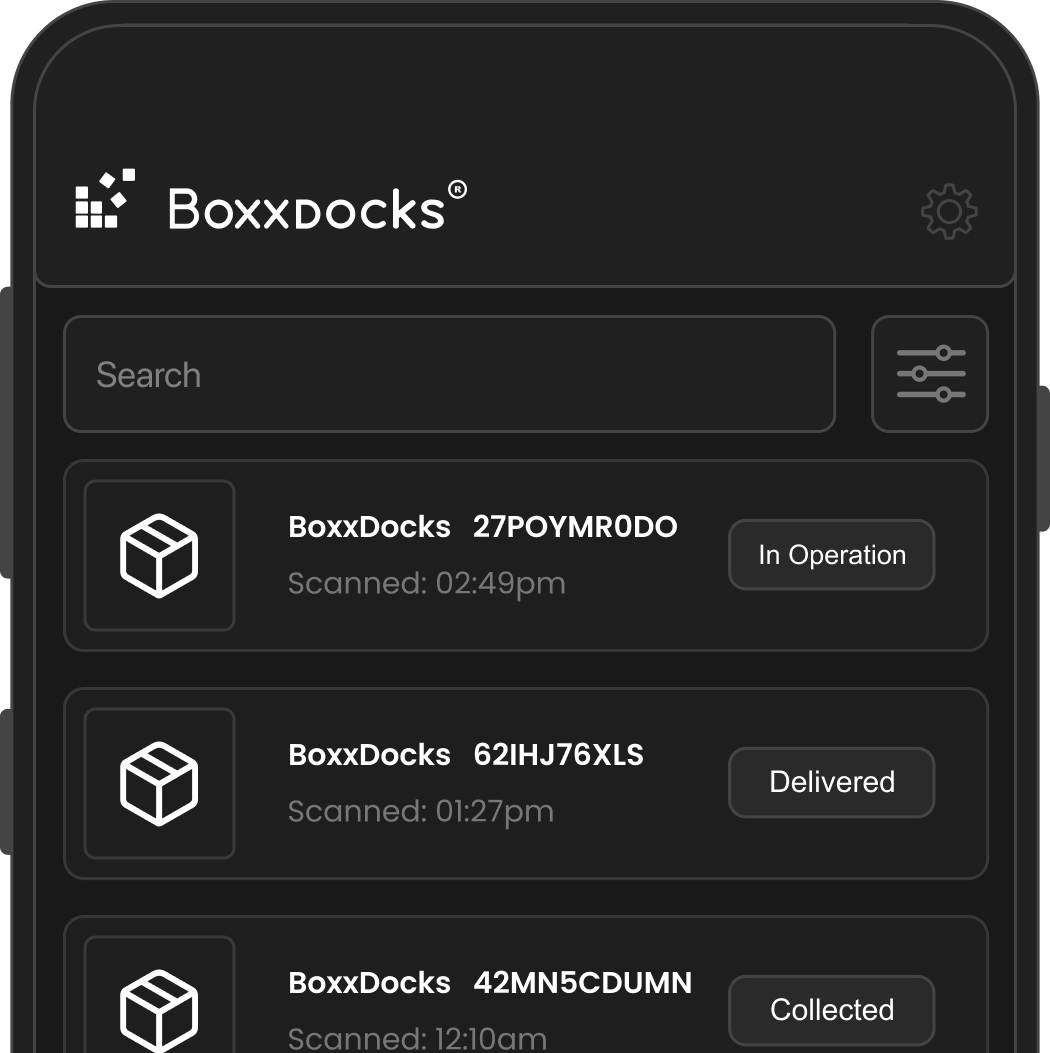
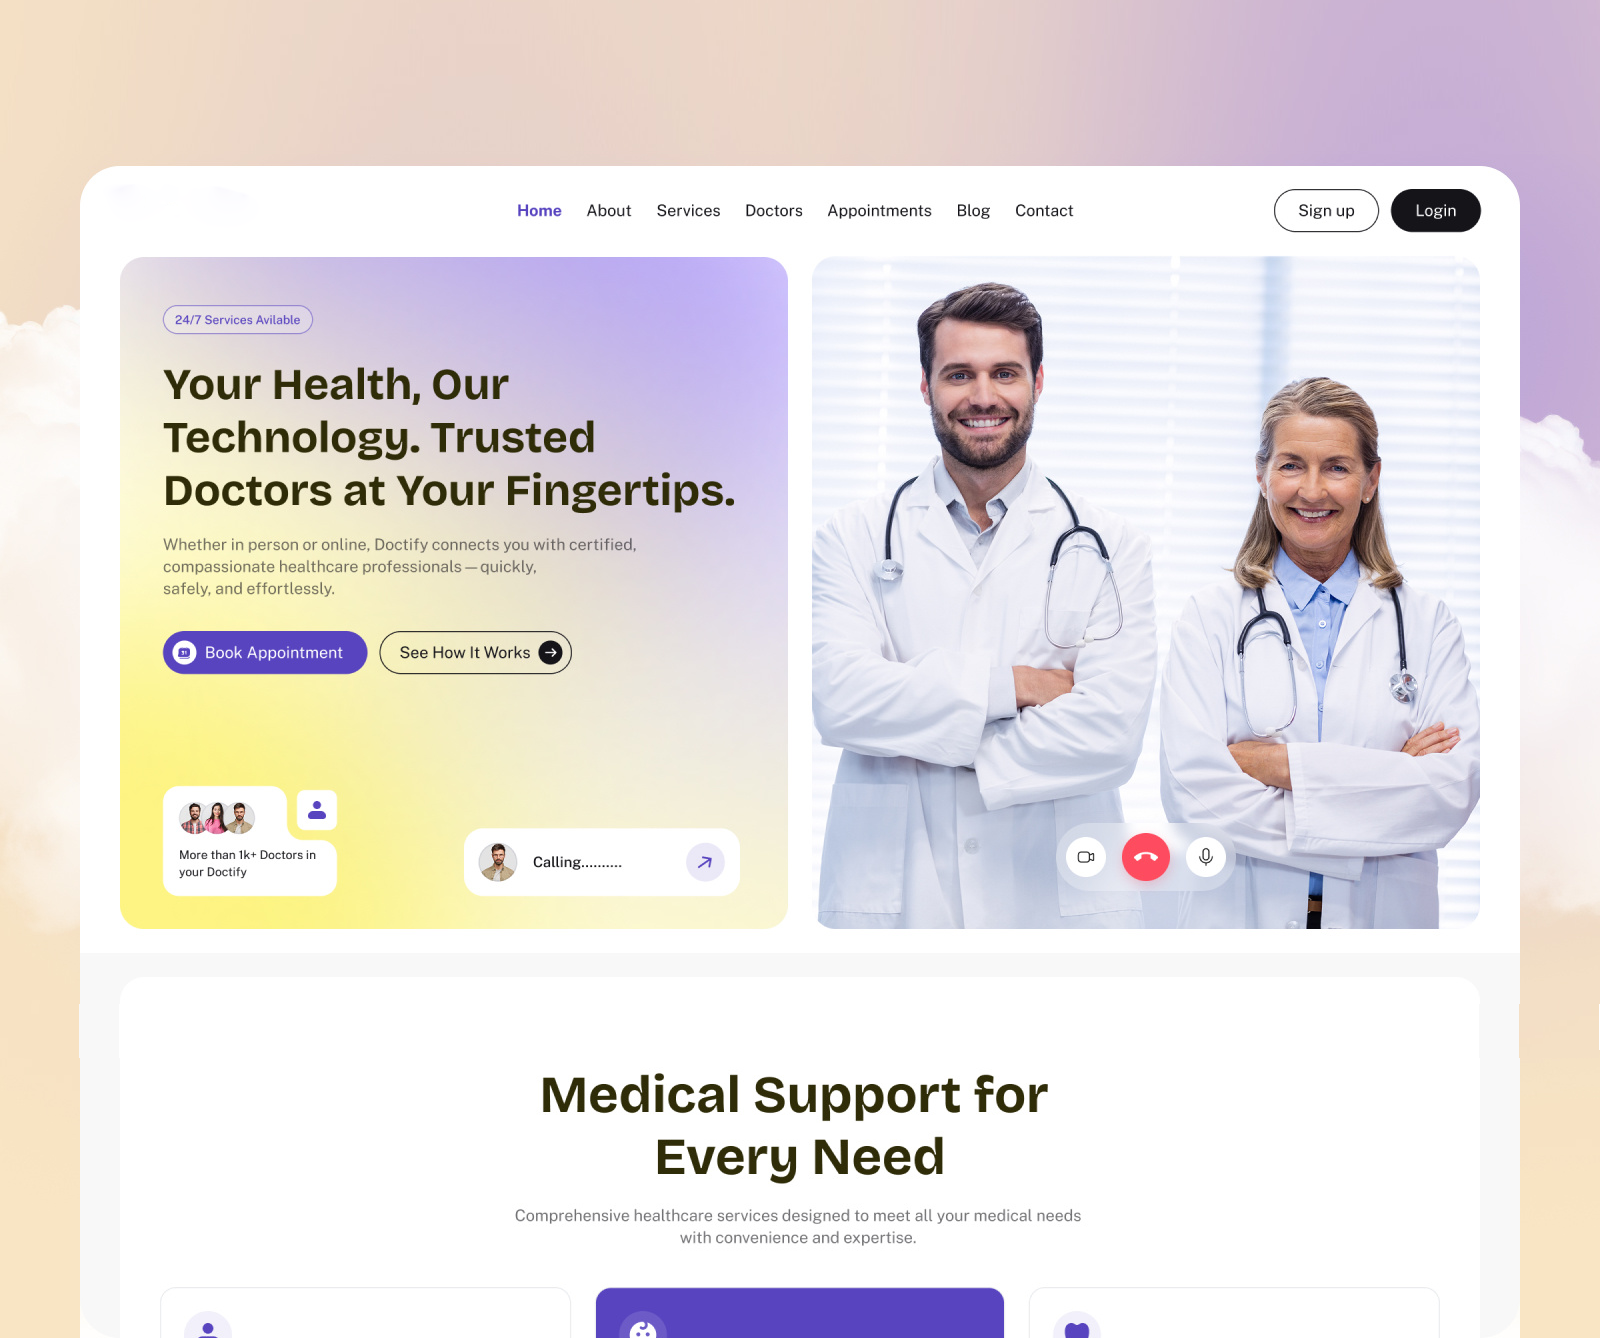
BoxxDocks AI Asset Tracking Platform
The Challenge
Asset tracking was manual, error-prone, and scattered across disconnected systems. The client had no central view of asset movement, no real-time location data, and no way to generate instant reports for multiple enterprise clients from one platform.
Our Approach
We built BoxxDocks as an AI-enabled asset lifecycle platform with QR/NFC scanning, real-time dashboards, geolocation tracking, and a RAG-powered conversational engine that lets users query live operational data in plain English instead of digging through dashboards.
The Result
- Real-time inventory tracking across warehouses, transit, and delivery
- AI query engine for natural language insights
- LLM-powered reporting with anomaly detection
- Complete audit trail with location, timestamp, and status
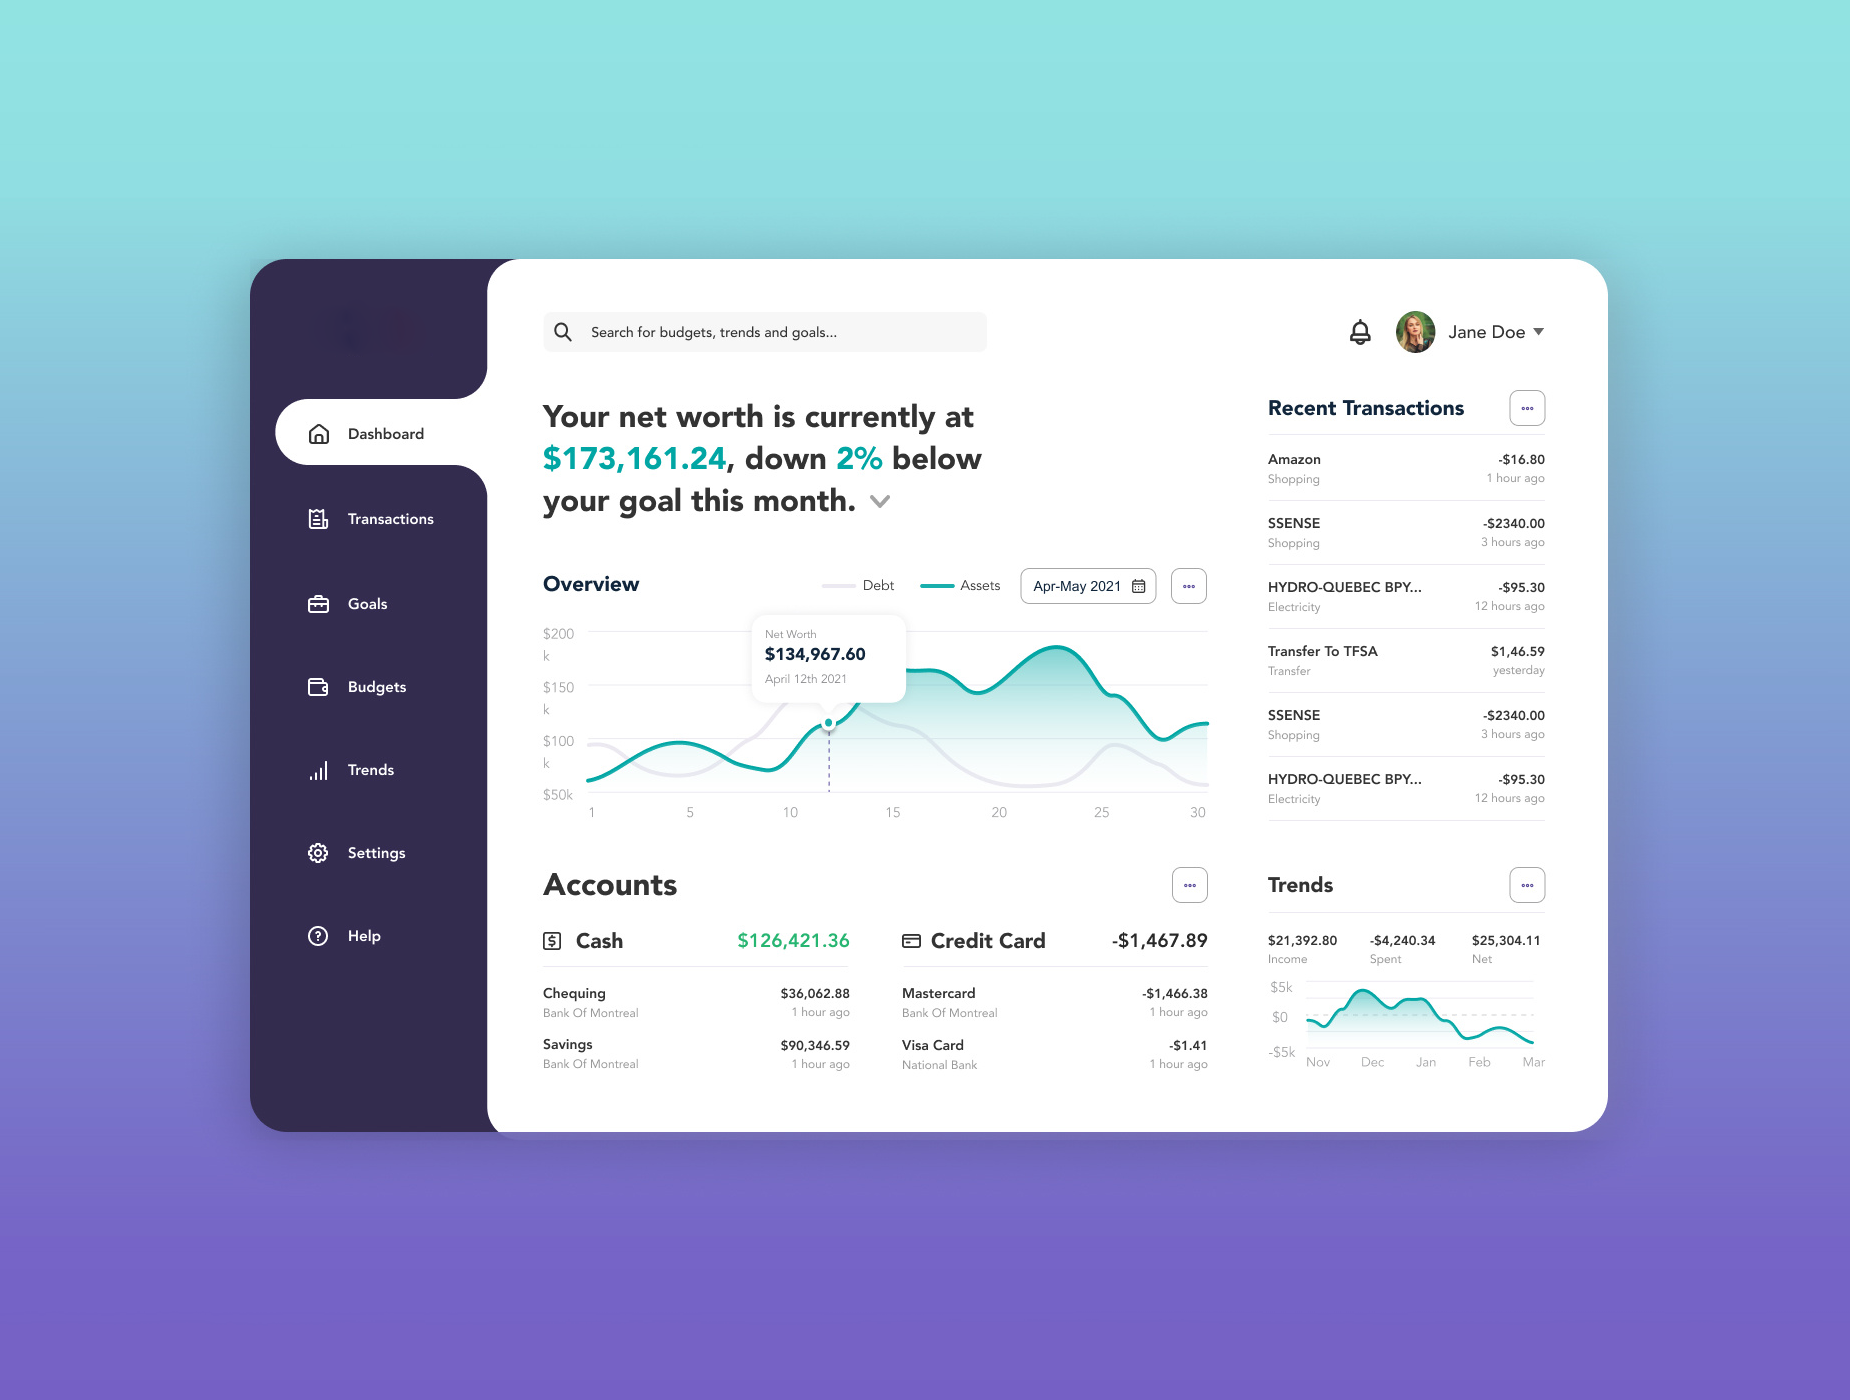
Parity AI AI Finance Platform
The Challenge
Personalized financial advice was expensive and limited to periodic meetings. Users had no way to bring banking, investments, debt, and insurance into one platform with real-time, AI-driven guidance.
Our Approach
We built Parity AI as an always-on financial wellness platform. It securely pulls data from multiple sources, analyzes user behavior, forecasts outcomes, and delivers personalized recommendations, acting as a digital financial advisor rather than a budgeting app.
The Result
- AI-powered financial planning across banking, investments, and debt
- Personalized recommendations based on life events and behavior
- Integrated financial education with actionable insights
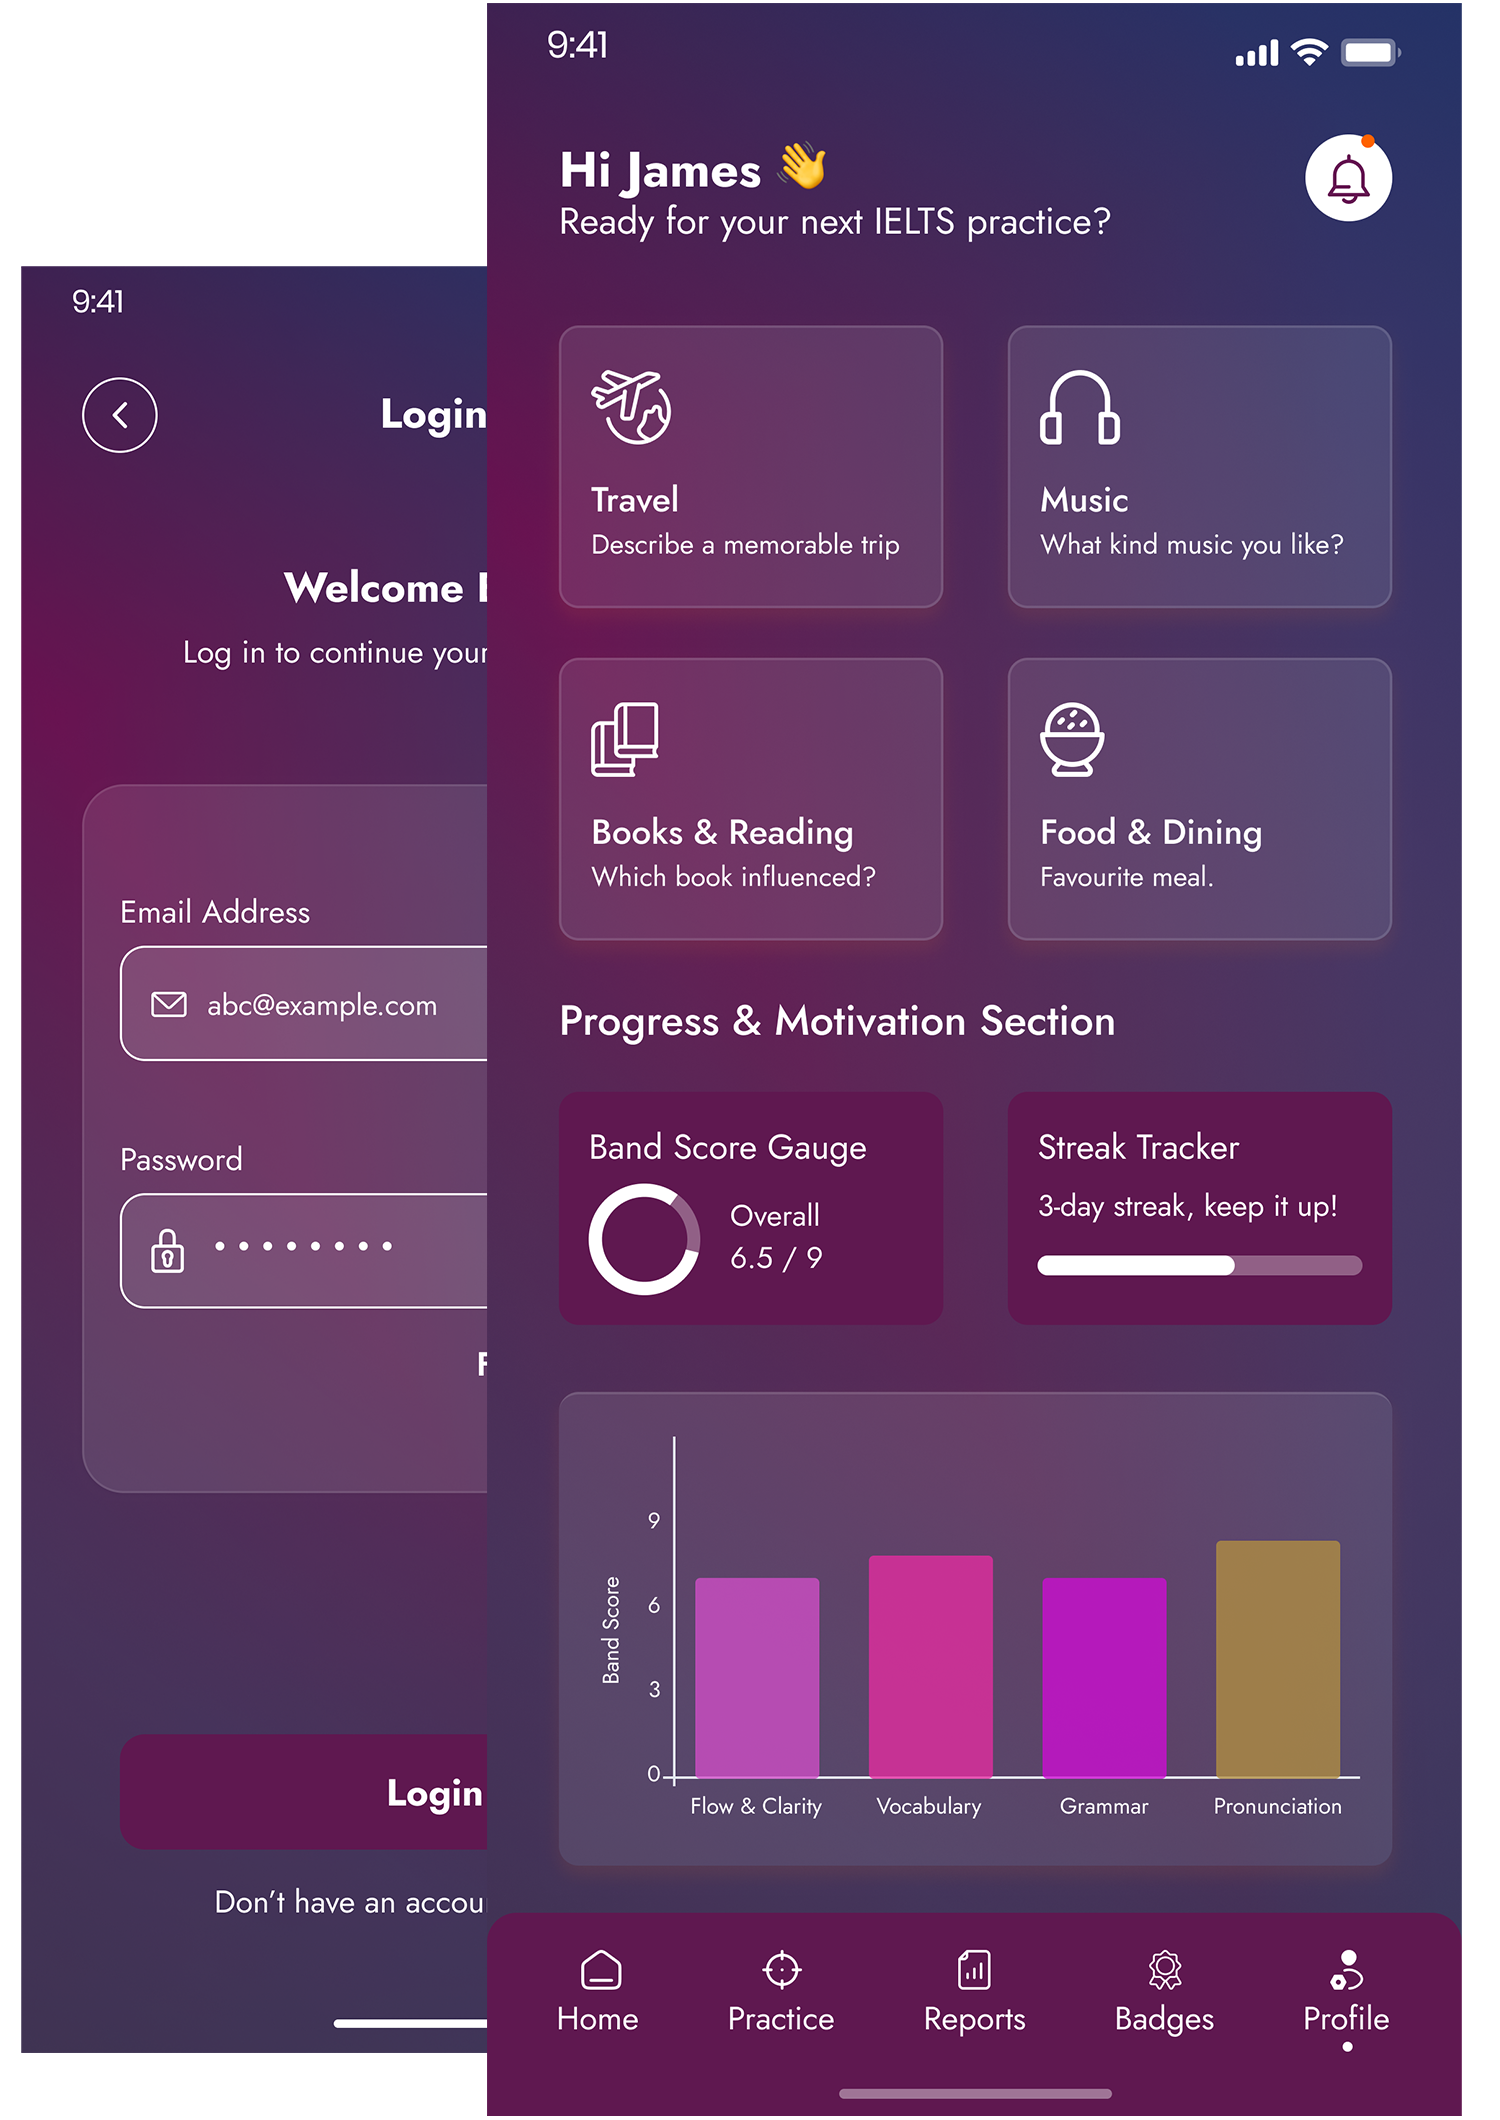
IELTS AI-Powered Speaking Evaluator
The Challenge
Human IELTS tutors cost $30-$80 per hour and have limited availability. Generic speaking apps lack the authentic Part 1/2/3 exam structure, pronunciation feedback, and band-aligned scoring. Learners had no way to get unlimited, exam-style practice at scale.
Our Approach
We built a full-stack AI platform with a lifelike AI avatar examiner, using a LangGraph and Gemini conversation engine, Google Cloud TTS with viseme lip-sync, Faster-Whisper speech recognition, and a 6-layer evaluation pipeline that scores all 4 IELTS criteria within ±0.5-1.0 band accuracy.
The Result
- 1,000+ concurrent users with 2–3s response latency
- 10x lower cost than human examiners
- 6 AI microservices with model preloading
- No-code admin panel for quick content updates
Health E Livin AI Wellness Platform
The Challenge
People struggling with mental health had no single place to access trusted information, take confidential assessments, and find providers without stigma or privacy concerns.
Our Approach
We built Health E Livin as an AI-powered mental wellness app with a conversational AI assistant, anonymous screenings, an evidence-based resource library, and geolocation-based provider discovery, all running on privacy-first cloud infrastructure.
The Result
- AI knowledgebase for natural language mental health support
- Confidential assessments with personalized wellness insights
- Location-based provider discovery for professional care
- Privacy-first architecture with encrypted data management
Hire generative AI engineers to build scalable, intelligent AI applications
Our generative AI developers deliver end-to-end LLM, RAG, and multimodal AI solutions tailored to your business goals, helping companies in the US and worldwide automate faster, cut operational costs, and keep pace with a fast-moving AI landscape.
Tech stack our generative AI developers use to build intelligent solutions
Hire generative AI developers who work with leading LLMs, orchestration frameworks, vector databases, and cloud AI platforms to build scalable, secure, production-ready generative AI applications.
 Python
 TypeScript
 FastAPI
 Node.js
 LangChain
 LangGraph
 LlamaIndex
 CrewAI
 AutoGen
 OpenAI Agents SDK
 MCP (Model Context Protocol)
 Claude
 Gemini
 Llama
 Mistral
 DeepSeek
 Hugging Face
 Midjourney
 Pinecone
 Weaviate
 Qdrant
 Chroma
 pgvector
 FAISS
 Elasticsearch
 Redis
 AWS Bedrock
 Azure AI Foundry
 Vertex AI
 Databricks
 Snowflake
 Docker
 Kubernetes
 MLflow
 Arize Phoenix
 Evidently AI
 NeMo Guardrails
 vLLM
 Grafana
Why choose Xicom to hire dedicated generative AI developers in India?
Hire generative AI engineers from Xicom for deep LLM expertise, flexible engagement models, and cost-efficient delivery, backed by a secure, well-defined approach to building production-ready generative AI solutions.
Team control
Direct access to your team for discussions anytime.
Data security
Strict adherence to data protection and confidentiality.
Flexible hiring
Hourly, part-time, or full-time models.
Strict NDA
Your business data stays fully protected.
24/7 support
Dedicated teams monitor performance round the clock.
Quality delivery
97% first-time-right code submission, every sprint.
Agile process
Faster, predictable delivery via iterative sprints.
Transparency
Real-time updates and full project visibility.
How to hire generative AI engineers in India from Xicom
Hiring dedicated generative AI developers from Xicom takes four simple steps, and you can onboard engineers skilled in LLM integration, RAG pipelines, fine-tuning, and multimodal AI frameworks.
-
Post Your Project Requirements
Share your business goals, technical specifications, and AI development needs with our experts. They'll match you with generative AI developers who fit your use case, industry, and deployment environment.
-
Select Developers' CV
Review curated CVs of our generative AI developers and evaluate their experience in LLM fine-tuning, RAG architecture, AI agent development, or multimodal AI to find the right fit.
-
Take Developer Interviews
Interview shortlisted developers to assess LLM proficiency, framework knowledge, prompt engineering skills, and communication before you make a final hiring decision.
-
Hassle-Free Onboarding
Onboard your selected generative AI developers through our quick onboarding process, with clear sprint planning and smooth collaboration from day one.
Our engagement models for hiring generative AI developers
As an AI development company, we offer flexible hiring models tailored to your project needs. Whether you need a dedicated generative AI developer full time or a team on fixed billing, there is a model that fits.
Fixed Price Model
Best for well-defined AI projects, this model ensures clear scope, budget predictability, and timely delivery without surprises.
- Upfront agreed cost and project scope
- Milestone-based progress tracking
- No hidden charges or overheads
- Reliable delivery timelines and outcomes
Most Popular
Dedicated Teams Model
Ideal for businesses seeking a long-term AI development partner, this model provides a dedicated team of AI engineers working exclusively on your project.
- Full control over team structure and workflows
- Highly scalable and cost-effective
- Direct communication with developers
- Increased focus and faster turnaround
Time & Material Model
Perfect for AI projects with dynamic requirements, this model offers agility, cost control, and adaptability to continuous innovation.
- Flexible billing based on actual efforts
- Adjust resources and scope anytime
- Ideal for iterative and evolving projects
- Faster implementation and continuous optimization
AI Needs Assessment
Before any sourcing begins, the process starts with a thorough understanding of your AI initiative, covering intended use cases, data landscape, compliance considerations, and the technical depth each role genuinely requires to deliver results.
- Use cases, AI objectives, and success criteria defined
- Data sources, model preferences, and integration points identified
- Compliance, security, and deployment constraints noted
- Role seniority and specialist skills mapped out clearly
Talent Matching
Using the brief as a filter, suitable developers are identified based on hands-on generative AI experience that aligns with your specific requirements, prioritizing real delivery experience over surface-level familiarity with tools and frameworks.
- Matched against use case, stack, and domain experience
- Verified for depth across LLMs, RAG, agents, or multimodal AI
- Availability and time-zone compatibility confirmed upfront
- Only genuine fits put forward for client review
Technical Assessment
Shortlisted developers go through a structured technical review before the client speaks with them, covering AI architecture thinking, past project outcomes, and hands-on capability across the relevant stack.
- AI system design and architectural decisions reviewed
- Hands-on capability across relevant frameworks assessed
- Past generative AI project outcomes evaluated in depth
- Problem-solving approach and communication style noted

Client Interview & Selection
The final evaluation sits entirely with the client. Shortlisted candidates are made available for direct interviews, technical discussions, or portfolio walkthroughs, giving full confidence before any commitment is made.
- Interviews scheduled on your preferred platform and timeline
- Portfolio and past AI work reviewed directly with the candidate
- Follow-up technical questions handled without time pressure
- Final selection made entirely at the client's discretion
Contracts & Engagement Setup
With selection confirmed, the engagement is formalized quickly. All commercial terms, deliverables, and working arrangements are documented clearly so both sides begin with complete alignment and no ambiguity.
- Engagement model finalized: dedicated, part-time, or fixed-scope
- Commercial terms, rates, and payment structure agreed
- Deliverables, milestones, and review cadence documented
- NDAs, IP ownership, and compliance requirements addressed

Delivery & Ongoing Support
Once underway, delivery follows a structured rhythm with regular visibility into progress. The team stays engaged beyond launch, handling monitoring, iteration, and scaling as your AI initiatives grow and evolve over time.
- Structured sprints with consistent progress visibility
- Direct developer access through your preferred channels
- Post-deployment monitoring, updates, and optimization included
- Engagement scaled up or adjusted as requirements shift
Client testimonials and reviews showcasing the value we consistently deliver
Explore how our clients describe their journey with us, reflecting strong collaboration, effective execution, and consistent outcomes delivered across engagements. See how our delivery framework ensures consistency from initiation through to successful completion.
❝
Parity AI
We came to Xicom with an ambitious goal: make institutional-grade financial planning accessible to everyone through AI. Xicom went beyond the brief, blending conversational AI and predictive analytics into an effortless platform. Parity AI is exactly what we envisioned.
❝
RadioFX
Xicom took the time to understand what our stations and listeners actually need, building something tailored rather than generic. Live chat and polls are now core to how we connect with our audience — the app has become a true extension of our on-air presence.
❝
StudyBuddy
Xicom built exactly what our students needed: a secure space to connect, collaborate, and find tutoring support in one place. Their understanding of student behavior shows in how naturally everything fits together — StudyBuddy is something students genuinely rely on.
❝
BoxxDocks
Xicom helped us bring BoxxDocks to life exactly as we envisioned it. Their team understood the complexity of AI powered real-time asset tracking and delivered a platform that's both powerful and genuinely easy to use.
❝
TodayFit
We are very happy with their services. I cannot recommend them highly enough. The value, ability, and delivery that we have seen has been superb, and we look forward to continuing this relationship.
❝
SmartVend AI
Their team built SmartVend from the ground up, combining hardware integration, real-time inventory sync, and a centralized dashboard that completely changed how we operate. We couldn't have asked for a more capable technical partner.
❝
Tap Retail
Partnering with Xicom to develop our Tap Retail app and website was one of the best decisions we made. Their team demonstrated exceptional professionalism, technical expertise, and a deep understanding of our business goals.
❝
GoGmGo
Partnering with Xicom was a game-changer for us. They didn't just build software, they helped us redefine how we run our business. Their proactive support and deep domain knowledge gave us the confidence to innovate faster.
❝
DENVEN
Working with Xicom has been a transformative experience. Their team quickly understood our challenges and delivered a scalable, intuitive solution. I highly recommend Xicom to any organization seeking future-ready, high-performance digital products.
Top tech insights of our blog
Explore the latest tech stories & news
✦ AI-First Company
Deep Insights into Emerging Technology and Innovation!
Stay ahead in the digital world with our latest insights covering AI trends, industry developments, and expert advice on building smarter businesses.
1800+
Projects
20+
Years Experience
Frequently Asked Questions
What roles do Xicom's Generative AI developers perform?
Xicom's Generative AI developers handle everything from selecting and integrating the right foundation model for your use case to building RAG pipelines, fine-tuning LLMs on domain-specific data, and deploying production-ready AI applications. They also design AI agents, build multimodal systems, and work closely with your existing tech team to ensure seamless integration with your current infrastructure.
How much does it cost to hire a Generative AI developer from Xicom?
Xicom's generative AI developers are available at hourly rates from $25 to $45, depending on experience level, tech stack specialization, and engagement model. That makes Xicom a cost-effective option for businesses in the US, UK, Australia, and Canada that want production-ready GenAI solutions without the overhead of local hiring. Share your requirements and we will recommend the right fit for your budget.
How can Generative AI benefit my business?
Generative AI can reduce manual effort across content creation, customer support, document processing, code generation, and knowledge management. When built right, it does not just save time. It creates new capabilities your teams did not have before, like instant access to institutional knowledge, automated report drafting, or AI assistants that understand your products and processes. Xicom's developers help you identify where Gen AI creates the most measurable impact for your specific business.
What technical skills do Xicom's Generative AI developers have?
Our developers are proficient in Python, LangChain, LangGraph, LlamaIndex, and AutoGen for orchestration. They have hands-on experience with foundation models including OpenAI GPT, Claude, Gemini, Mistral, Llama, and DeepSeek. On the infrastructure side, they work with vector databases like Pinecone, Weaviate, and ChromaDB, and cloud platforms including AWS Bedrock, Azure OpenAI, and Google Vertex AI. They are also experienced in fine-tuning techniques like LoRA and PEFT, and evaluation frameworks for testing output quality in production.
Why should I hire Generative AI developers from Xicom specifically?
A few reasons clients consistently come back to Xicom. First, you get developers with real project experience across multiple industries, not junior talent learning on your budget. Second, hiring from India through Xicom can save up to 65% compared with equivalent talent in Western markets. Third, Xicom handles the screening, vetting, and ongoing management so you spend less time on hiring and more time on building. Fourth, every engagement is backed by an NDA and clear IP ownership terms from day one.
How does Xicom handle data privacy and security?
Every engagement begins with a signed NDA before any project details are shared. Xicom follows strict data handling protocols throughout the development lifecycle. Client data is never used to train or fine-tune models without explicit written authorization. Xicom holds ISO/IEC 27001, ISO/IEC 42001, and SOC 2 Type II certifications, and for clients with specific requirements around GDPR, HIPAA, or CCPA, the team adapts its data handling approach accordingly.
What ongoing support can I expect after the project goes live?
Xicom provides post-deployment support that includes performance monitoring, prompt optimization, vector database updates, and model upgrades as newer versions become available. If something breaks or degrades in production, the team responds quickly. Most clients on dedicated engagements retain their developer for ongoing iteration rather than treating the launch as the finish line.
Every award marks a milestone in our journey of excellence
As an AI-first digital engineering company, Xicom has earned global recognition for delivering innovative, scalable, and high-performing technology solutions. Our awards reflect the trust of clients and industry leaders alike.