Oct 21, 2026 Artificial Intelligence
Quick Answer
Enterprise AI cost goes far beyond the API or GPU bill. Total cost of ownership includes infrastructure, model and token fees, agent orchestration, data engineering, talent, maintenance, compliance and legacy integration. Indicative build costs range from about $20K for a scoped chatbot to $500K or more for a multi-agent system, plus ongoing run costs.
Enterprise AI cost is rarely the number on the first invoice. The API bill or GPU quote is easy to see, so it gets the attention in budget meetings. The larger costs sit around it: data pipelines, evaluation, monitoring, security, compliance evidence and the engineers who keep the system reliable in production.
The scale of spending makes this gap expensive. Gartner forecasts worldwide AI spending of $2.7 trillion in 2026, up 49.5% year over year. Yet MIT’s NANDA initiative found that about 95% of enterprise generative AI pilots delivered little or no measurable P&L impact.
This guide breaks enterprise AI cost into its real components, gives planning ranges by project type, and shows how to estimate and control total cost of ownership before you build.
What Makes Up the Total Cost of Enterprise AI
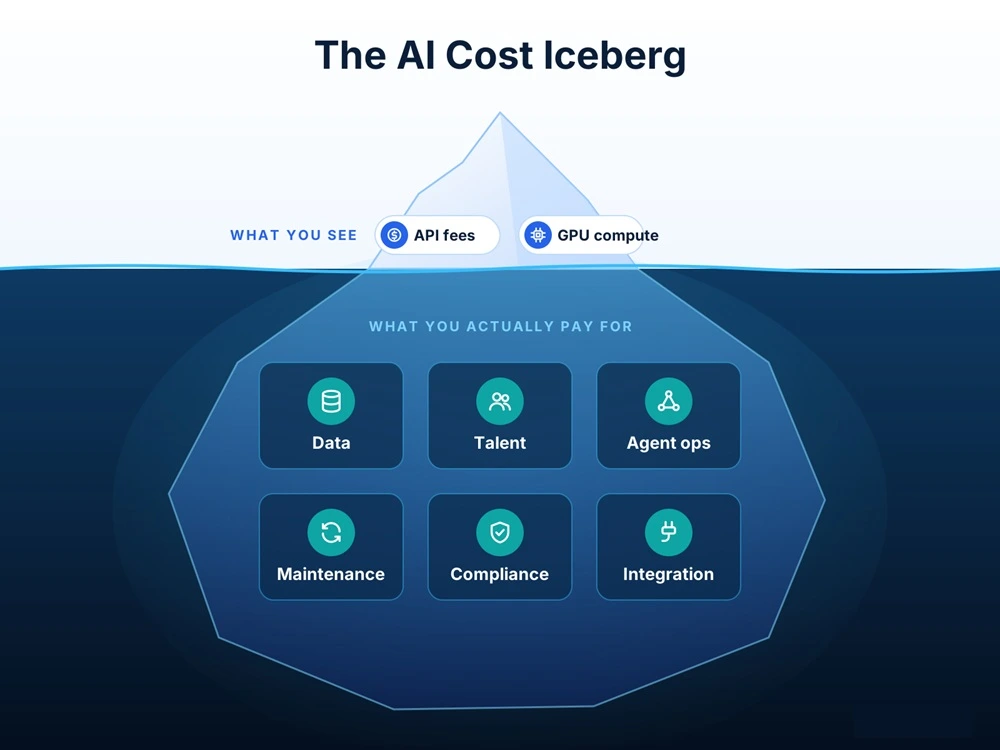
The total cost of enterprise AI spans eight components, and only the first two show up cleanly on a vendor invoice. A realistic AI TCO model budgets for all eight from day one.
- Infrastructure: GPUs, cloud instances, storage, networking and power for training and inference.
- Models and tokens: API fees for proprietary models or the hosting cost of open models.
- Agent orchestration: the harness around the model, including routing, retries, tool permissions, logging and fallbacks.
- Data engineering: collection, cleaning, labeling, pipelines, vector databases and data governance.
- People: AI engineers, data engineers, MLOps, product owners and domain experts.
- Maintenance: monitoring, evaluation, drift detection, retraining and version control.
- Compliance and security: documentation, audit trails, access control and regulatory evidence.
- Integration: connecting AI to ERP, CRM, legacy databases and existing workflows.
Compute costs scale with usage. People, data and compliance costs scale with the number of workflows in production. Both need separate lines in the budget.
Build vs Partner vs Buy: How Your Approach Shapes Cost
The sourcing decision sets the cost curve for everything that follows. Buying a packaged AI product is cheapest to start but limits control. Building fully in-house gives maximum control but carries the highest fixed cost. Partnering with an AI development company sits between the two.
| Approach | Upfront cost profile | Ongoing cost profile | Control | Typical time to first value | Best fit |
|---|---|---|---|---|---|
| Buy (SaaS or embedded AI) | Low: licenses and setup | Per-seat or usage fees that grow with adoption | Limited | Weeks | Standard use cases such as meeting notes or support deflection |
| Partner (AI development company) | Medium: scoped project fee | Shared: infra plus a lean internal owner team | Shared, with code ownership | 2 to 4 months for a POC or MVP | Custom workflows without a full in-house AI team |
| Build (in-house team) | High: hiring, platform, tooling | High: salaries plus platform engineering | Maximum | 6 to 12+ months | Core differentiating AI where IP and data control are critical |
Timelines and profiles above are indicative planning guidance, not benchmarks. Three questions narrow the choice quickly: is this an experiment or a long-term capability, what is the acceptable budget overrun, and is there a measurable KPI the AI must move?
AI Infrastructure Costs: Compute, Hosting and Inference
he total cost of enterprise AI infrastructure depends less on the GPU you pick and more on how busy you keep it. The same H100 can be cheap or ruinous depending on utilization, region and contract type.
Training vs Inference Costs
Training is a large, one-time or periodic spend. Inference is a recurring cost that grows with every user, query and agent step. Gartner expects inference to account for 59% of AI-optimized IaaS spending by 2027.
Most enterprises should not train foundation models at all. Fine-tuning an open model or adding retrieval-augmented generation (RAG) over company data costs a fraction of full training and covers most business use cases.
Cloud vs On-Premises vs Hybrid
GPU pricing varies widely by provider. As of October 2026, AWS lists its 8-GPU p5.48xlarge at $55.04 per hour on demand, about $6.88 per H100-hour, while Google Cloud’s A3 works out to about $11.06 and Azure’s ND H100 v5 to about $12.29 per H100-hour. Specialist GPU clouds publish on-demand rates roughly in the $2 to $4 range per GPU-hour.
| Hosting model | Cost behavior | Governance and control | Best fit |
|---|---|---|---|
| Hyperscaler on demand | Highest hourly rate, no commitment | Strong: existing IAM, audit and residency controls | Spiky or early-stage workloads |
| Hyperscaler reserved or capacity block | Lower rate, requires committed usage | Strong | Predictable production inference |
| Specialist GPU cloud | Lowest hourly rate | Weaker: extra work to move data and controls | Portable workloads such as batch inference, fine-tuning runs |
| On-premises or colocation | High upfront capex, low marginal cost | Maximum | Sustained high-utilization workloads, strict data residency |
| Hybrid | Mixes the above per workload | Balanced | Most enterprises at scale |
The cheapest GPU hour is not the cheapest operating model. To keep the total cost of enterprise AI infrastructure under control, keep regulated workloads where governance already exists, and move portable workloads to lower-cost capacity.
When Self-Hosting Makes Sense
Self-hosting open models pays off only when sustained utilization keeps the GPUs busy. At low or uneven volume, an idle GPU still has to be financed, powered and monitored, so a managed API usually costs less. Before comparing API spend with GPU prices, add platform engineers, failover capacity, monitoring and the months when demand falls below forecast.
Load-test with real prompt lengths, output lengths and concurrency. Latency often stays flat and then climbs sharply at a concurrency threshold, so size capacity around peak load rather than average utilization.
Also Read: AI Development Cost
Model and Token Costs: Choosing the Right Model for Each Task
The cheapest model that passes your evaluation set is the right model for that task. Sending every request to a frontier model is the most common source of avoidable token spend.
A practical routing approach:
- Commodity tasks such as classification, extraction, tagging and short summaries go to a small or mid-tier model, often open source.
- Reasoning-heavy tasks where an error affects credit, pricing, safety or a customer commitment go to a frontier model.
- Repeated context is cached, and prompts are trimmed so the model reads only what the next step needs.
Build a task-specific eval set before choosing models. Without it, teams default to the most capable model because they cannot prove a cheaper one is good enough. Track cost per accepted output, not cost per million tokens, since a cheap model that fails half the time is not cheap.
When a narrow, high-volume task needs domain accuracy that prompting cannot reach, fine-tuning a smaller model often lowers both latency and per-request cost.
Agentic AI Costs: Pricing per Successful Task
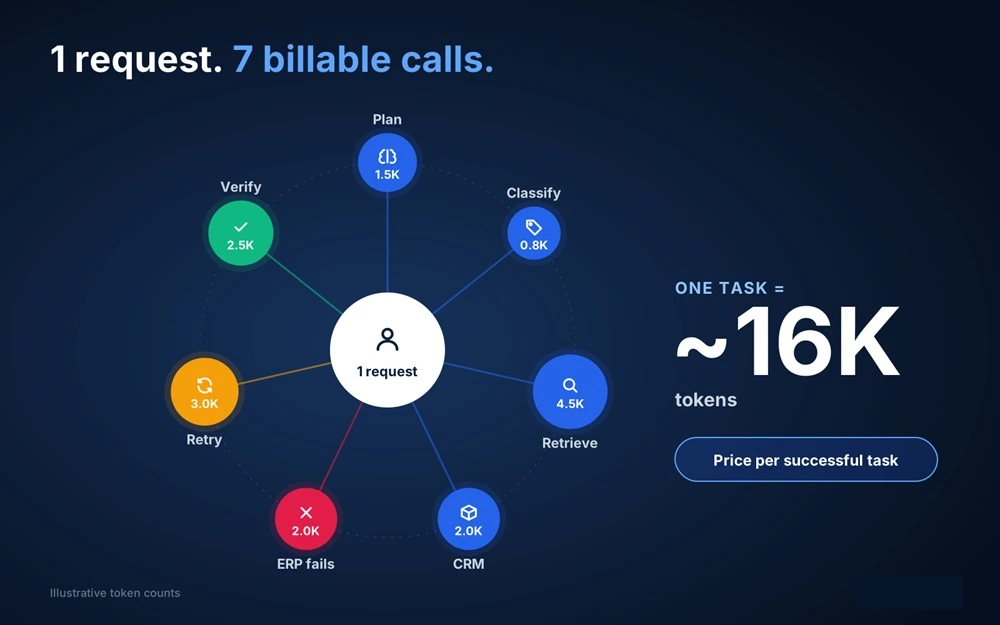
Agentic AI cost should be measured per successful task, not per request or per token. A user sees one request, but the agent may classify it, retrieve context, call several tools, retry a failed step and run a verification pass. Finance pays for every one of those calls.
Cost is the main reason agent projects stall. Gartner predicts over 40% of agentic AI projects will be canceled by the end of 2027 due to escalating costs, unclear business value or weak risk controls.
Retries, Loops and ContextGrowth
Small failure rates compound at volume. A retry rate that looks harmless in a demo becomes a large line item when the workflow runs tens of thousands of times a month, because each retry carries more context and another tool call.
A production agent harness controls this by:
- Capping loop depth and total steps per task
- Compacting older context and pruning redundant tool output
- Retrieving only what the next step needs
- Stopping when another pass adds no measurable value
- Logging every step so cost per task can be traced
Reasoning Budgets Matched to Business Risk
Not every task deserves the same reasoning depth. Set a higher token and step budget where a wrong answer changes credit, pricing, a customer promise, a compliance decision or a production action. Keep low-risk tasks on short, cheap paths.
The harness itself is a cost center. Someone must own routing, evaluations, tool permissions, fallbacks and rollback, and that work does not appear in any model’s price per million tokens. Budget for it explicitly when scoping AI agent development.
Data Engineering and Preparation Costs
Data work is usually the largest hidden line in enterprise AI cost. The first months of many AI programs go to finding, cleaning and connecting data before any model delivers value. That work is not waste: it decides whether the model has anything trustworthy to act on.
| Data cost area | What it covers | Main cost drivers |
|---|---|---|
| Collection and integration | Connectors, ETL and APIs from ERP, CRM, documents and logs | Number of source systems, data formats, legacy access |
| Cleaning and preprocessing | Deduplication, schema alignment, PII masking | Data quality, volume, sensitivity |
| Labeling and annotation | Training and eval labels, human review | Domain expertise needed, label complexity |
| Vector and retrieval layer | Chunking, embeddings, vector database, re-indexing | Corpus size, update frequency, query volume |
| Storage and lifecycle | Hot, warm and archive tiers, retention rules | Data growth, access patterns |
| Governance and lineage | Access control, lineage tracking, audit evidence | Regulatory scope, number of data owners |
Scope data work to the workflow being automated. Trying to modernize every data system before the first use case burns budget, while skipping preparation entirely creates technical debt that surfaces in production.
AI Team and Talent Costs
People are often the largest recurring line in an AI budget, especially in the first 12 to 24 months. The scarce skill is not model research. It is the engineering that makes the whole system reliable in production: data pipelines, evaluation, serving, monitoring and security.
A lean production AI team typically includes:
- AI or ML engineers for model integration, prompting, fine-tuning and evaluation
- Data engineers for pipelines, retrieval and data quality
- An MLOps or platform engineer for serving, monitoring and cost controls
- An AI product manager who owns the business outcome
- Domain experts who define what a correct answer looks like
Strong data engineering and product ownership usually create more value early than adding ML specialists.
In-House vs Offshore vs Hybrid Teams
| Delivery model | Cost profile | Control | Speed to start | Best fit |
|---|---|---|---|---|
| In-house US or EU team | Highest: full salaries, benefits, recruiting, retention | Maximum | Slow: months of hiring | Core IP, long-term AI platforms |
| Offshore dedicated team (e.g. India) | Lower: blended rates well below US salaries | High, with dedicated engineers and your processes | Fast: weeks | Build and scale phases, MLOps, data engineering |
| Hybrid | Balanced: in-house leads plus offshore delivery | High | Fast | Most enterprises scaling beyond the first use case |
The hybrid model keeps architecture, product ownership and domain decisions in-house while a dedicated offshore team handles build, testing and operations. Enterprises often start this way by choosing to hire AI developers through a dedicated team model.
Maintenance, Monitoring and Model Drift
An AI system starts losing accuracy the day real-world data begins to differ from what it was built on. Maintenance is a permanent budget line, not a post-launch afterthought.
Recurring maintenance costs include:
- Evaluation and monitoring: continuous eval runs, quality dashboards and alerting on output drift
- Model updates: re-prompting, targeted fine-tuning or swapping to a newer model version when a provider deprecates one
- Retrieval upkeep: re-indexing documents and refreshing embeddings as source content changes
- Version control and rollback: tracking model, prompt and data versions so a bad release can be reversed quickly
- Security patching: reviewing API keys, access policies, vector store permissions and prompt-injection defenses
AI-generated code adds its own maintenance cost. Every AI-written module should have a named human owner, tests that prove intended behavior and the same review standard as human-written code, or ownership erodes as teams change.
Compliance and Governance Costs
Compliance is now a fixed part of enterprise AI cost for any system that touches regulated decisions or EU users. The cost is mostly people and process: documenting systems, keeping evidence, and proving human oversight.
Under the EU AI Act, standalone high-risk systems in Annex III, such as those used for hiring, credit and access to essential services, must meet high-risk requirements by December 2, 2027. Article 99 sets fines of up to EUR 35 million or 7% of worldwide annual turnover for prohibited practices, and up to EUR 15 million or 3% for breaches of most other obligations.
Compliance cost lines to budget for:
- Mapping which workflows fall into high-risk categories
- Technical documentation, risk management and logging
- Data lineage records showing which data trained or grounded which model version
- Human oversight design and audit-ready evidence
- Overlapping regimes such as GDPR, HIPAA and sector rules
Building governance in from the start costs far less than retrofitting it into a live system. A focused AI governance consulting engagement can map scope before build.
Legacy Integration Costs
Integration is where many AI budgets overrun, because the AI must read from and write to systems that were never designed for it. Ripping out core systems to make room for AI rarely pays back.
Lower-cost integration patterns:
- API and middleware layer: an integration layer exposes legacy data and actions to AI services without changing core applications.
- Modular AI services: focused capabilities such as document classification or anomaly detection plug in through standard APIs.
- Read first, write later: start with AI that reads and recommends, then add write-back actions once accuracy and controls are proven.
Integration effort depends on how many systems the workflow touches, whether those systems have usable APIs, and how clean their data is. Assess all three during scoping, not after the model works in a demo.
Enterprise AI Cost by Project Type
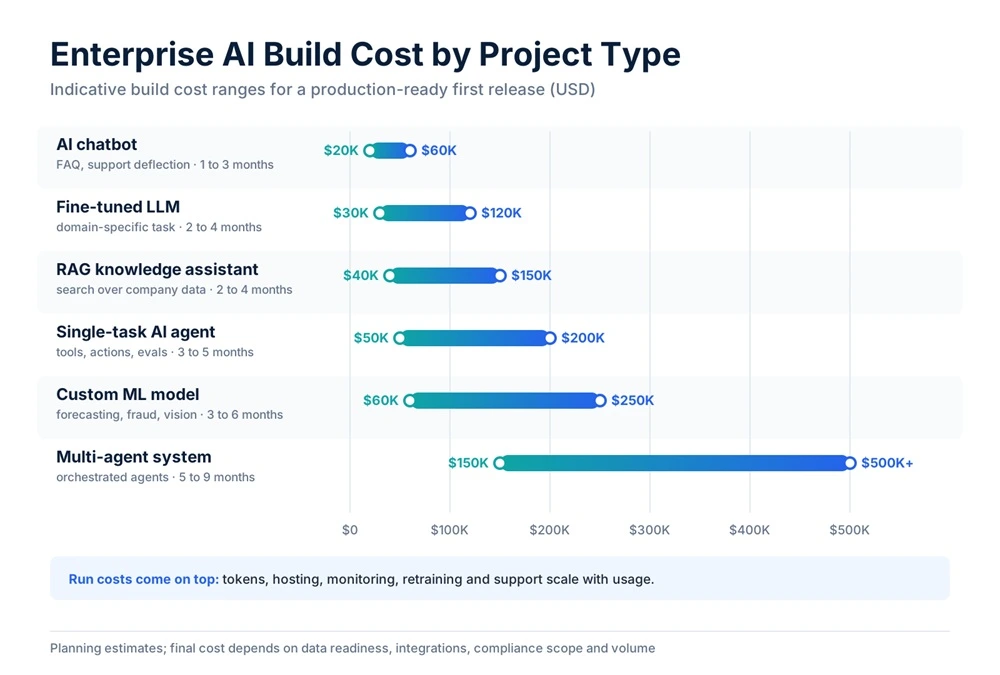
Build cost and run cost differ sharply by project type. The ranges below are indicative planning ranges for a production-ready first release delivered with a blended onshore and offshore team. Final cost depends on data readiness, integrations, compliance scope and volume.
| Project type | Typical build cost range (USD) | Main monthly run cost drivers | Typical timeline | Best-fit delivery model |
|---|---|---|---|---|
| AI chatbot (FAQ, support deflection) | $20K to $60K | Token usage, conversation volume, monitoring | 1 to 3 months | Partner or buy |
| RAG knowledge assistant | $40K to $150K | Tokens, vector database, re-indexing, access control | 2 to 4 months | Partner |
| Single-task AI agent | $50K to $200K | Tokens per task, tool calls, retries, evaluation | 3 to 5 months | Partner or hybrid |
| Multi-agent system | $150K to $500K+ | Orchestration, tokens across agents, observability, human review | 5 to 9 months | Hybrid |
| Custom ML model (forecasting, fraud, vision) | $60K to $250K | Inference compute, retraining, data pipelines | 3 to 6 months | Partner or hybrid |
| Fine-tuned LLM for a domain task | $30K to $120K | Hosting or API cost, periodic re-tuning, evals | 2 to 4 months | Partner |
Editor note: these ranges are planning estimates, not sourced statistics. Validate them with Xicom’s delivery or sales team before publishing.
A scoped AI POC or MVP is the lowest-risk way to replace these ranges with a real number for your workflow.
How to Estimate and Control AI Costs Before You Build
A reliable AI cost estimate starts with the workflow, not the model. Use this checklist before funding a build:
- Baseline the workflow today. Record time per task, people involved, error and escalation rates, and cost per transaction.
- Define success as a business metric. Name the one number the AI must move, such as handling time, approval cycle or cost per claim.
- Model two budgets. One for the pilot, one for full production volume a year later, including network traffic and compliance.
- Estimate volume and workload shape. Requests per month, prompt and output length, steps per agent task and peak concurrency.
- Build an eval set first. Use it to pick the cheapest model that meets the quality bar.
- Price hosting three ways. Hyperscaler on demand, reserved capacity and specialist or self-hosted options, adjusted for governance needs.
- Budget the hidden lines. Data preparation, evaluation, monitoring, security and the people who own them.
- Set cost guardrails. Per-task token caps, loop limits, alerts on spend anomalies and a monthly cost review.
- Map compliance scope. Check whether the use case falls under high-risk rules before design is locked.
Also Read: How Much Does it Cost to Develop an AI App
Measuring AI ROI at the Workflow Level
AI ROI is proven at the workflow level, against the baseline captured before the build. A polished demo is not a baseline. Track these metrics before funding each next phase:
| Metric | What it tells you |
|---|---|
| Cost per accepted task | True unit cost, including retries and failed outputs |
| Human minutes removed per task | Labor value the AI actually returns |
| Exception or retry rate | Reliability, and a leading indicator of hidden cost |
| Latency at production concurrency | Whether the system holds up under real load |
| Adoption rate | Share of eligible work actually routed through AI |
| Target business metric | The outcome the workflow was meant to move |
If the business metric does not improve, the other numbers are optimization details. Put a business owner, not only an engineering lead, in charge of the scorecard, and bring finance in from the start.
Conclusion
Enterprise AI cost is decided less by the model you choose and more by everything built around it. Infrastructure, agent orchestration, data engineering, talent, maintenance, compliance and integration together shape the real total cost of ownership. They also decide whether an AI initiative pays back.
The enterprises that control AI spend share a few habits:
- They baseline the workflow before building.
- They route each task to the cheapest model that passes evaluation.
- They price agents per successful task.
- They budget for the hidden lines from day one.
- They measure ROI against a business metric, not a demo.
Start with a scoped POC or MVP to replace estimates with real usage and cost data, then scale only what proves its value.
FAQs
1. How much does it cost to implement AI in an enterprise?
Enterprise AI implementation typically costs from about $20K for a scoped chatbot to $500K or more for a multi-agent system, before ongoing run costs. The final figure depends on data readiness, the number of integrations, compliance scope and usage volume. A POC or MVP is the most reliable way to turn these ranges into a real estimate.
2. What are the hidden costs of AI?
The hidden costs of AI are the expenses outside the model or API bill. They include data engineering, evaluation and monitoring, retraining, security, compliance documentation, legacy integration and the engineers who run the system. Together these often exceed visible compute and token spend, so they need their own budget lines from day one.
3. What is the total cost of ownership (TCO) for enterprise AI?
AI total cost of ownership is the full cost to build, run and maintain an AI system over its life. It covers infrastructure, model or token fees, agent orchestration, data, people, maintenance, compliance and integration. TCO should be modeled for both the pilot and full production volume, since costs change sharply as usage scales.
4. Is it cheaper to self-host an LLM or use an API?
An API is usually cheaper at low or uneven volume, because you pay only for what you use and avoid idle GPUs. Self-hosting becomes cheaper only when sustained utilization is high enough to cover hardware, failover, monitoring and the platform team. Load-test real workloads before switching.
5. Why does inference cost more than training over time?
Inference costs more over time because it runs every time someone uses the system, while training is a periodic expense. As users, queries and agent steps grow, inference spend grows with them. That is why hosting choices, model routing and caching have the biggest effect on the total cost of enterprise AI infrastructure.
6. How does the EU AI Act affect enterprise AI cost?
The EU AI Act adds documentation, risk management, logging and human oversight costs for high-risk systems. Standalone high-risk systems in Annex III must comply by December 2, 2027. Fines reach EUR 35 million or 7% of global turnover for prohibited practices, so building governance in early is far cheaper than retrofitting it.
Make your ideas turn into reality
With our AI & mobile app solutions