How Much Does It Cost to Develop an AI App? Full Breakdown, Factors & Estimations
AI app development cost ranges from $30,000 to $300,000+. See costs by complexity and use case, running costs, timelines, and tips to cut your budget.
Nov 9, 2026 Artificial Intelligence
Quick Answer
To evaluate an AI model, define what success means for the business, test the model on held-out data that reflects real usage, and measure task-specific metrics such as precision and recall for classification or faithfulness for LLMs. Then check robustness, fairness, latency, and cost, and keep monitoring the model in production. No single metric is enough. Reliable evaluation combines automated metrics, human review, and live monitoring.
An AI model that scores well in a notebook can still fail in production. It can misclassify the cases that matter most, invent facts with full confidence, slow down under real traffic, or slowly lose accuracy as user behavior changes. AI model evaluation is how you catch these problems before your users do.
This guide explains how to evaluate AI models from start to finish: the metrics that matter for each type of model, the methods teams use to test them, how LLM evaluation differs from traditional machine learning, and the best practices that keep a model reliable after launch.
AI model evaluation is the process of measuring how well a model performs its intended task, how reliably it behaves across different conditions, and whether it is safe, fair, and cost-effective enough to use in a real product. It covers the full life of the model, from comparing candidate models during development to monitoring the chosen model after deployment.
Good evaluation matters for four reasons:
Whether you are testing a fraud detection model, a computer vision system, or an LLM-powered assistant, the same process applies.
Start with the outcome the model should improve, such as fewer fraud losses, faster ticket resolution, or fewer manual reviews. Then decide which errors cost more. In medical screening, a missed case is far worse than a false alarm. In spam filtering, blocking a real email may be worse than letting some spam through. These trade-offs decide which metrics you prioritize.
Create a test set, often called a golden dataset, that the model never sees during training. It should reflect real inputs, including edge cases, rare classes, different user groups, and messy data. Check for data leakage, where test examples or near-duplicates slip into training data and make results look better than they are.
Pick a primary metric that reflects the business goal and a few supporting metrics that guard against blind spots. A classification model might use recall as its primary metric, with precision and latency as guardrails. The next section lists metrics by task type.
Compare the model against something simple: the current rule-based system, a basic statistical model, or the existing human process. A model is only worth deploying if it beats the baseline by a margin that justifies its cost and complexity.
Score the model on the test set and break results down by segment, such as region, customer type, language, or device. Strong average performance can hide poor results for an important group.
Check how the model handles noisy, unusual, or adversarial inputs. Compare error rates across demographic groups where that is relevant. For generative AI, test for harmful content, data leakage, and prompt injection.
Measure latency, throughput, memory use, and cost per request under realistic load. A highly accurate model that is too slow or too expensive for your traffic is not production-ready.
Before full rollout, run the model in shadow mode alongside the current system or launch an A/B test with a small share of traffic. This shows whether offline gains translate into better business results.
Track quality, drift, latency, and cost after launch, and set alerts for meaningful changes. Re-run your evaluation suite whenever you retrain the model, change a prompt, or switch model versions.
Also Read: AI App Development Cost
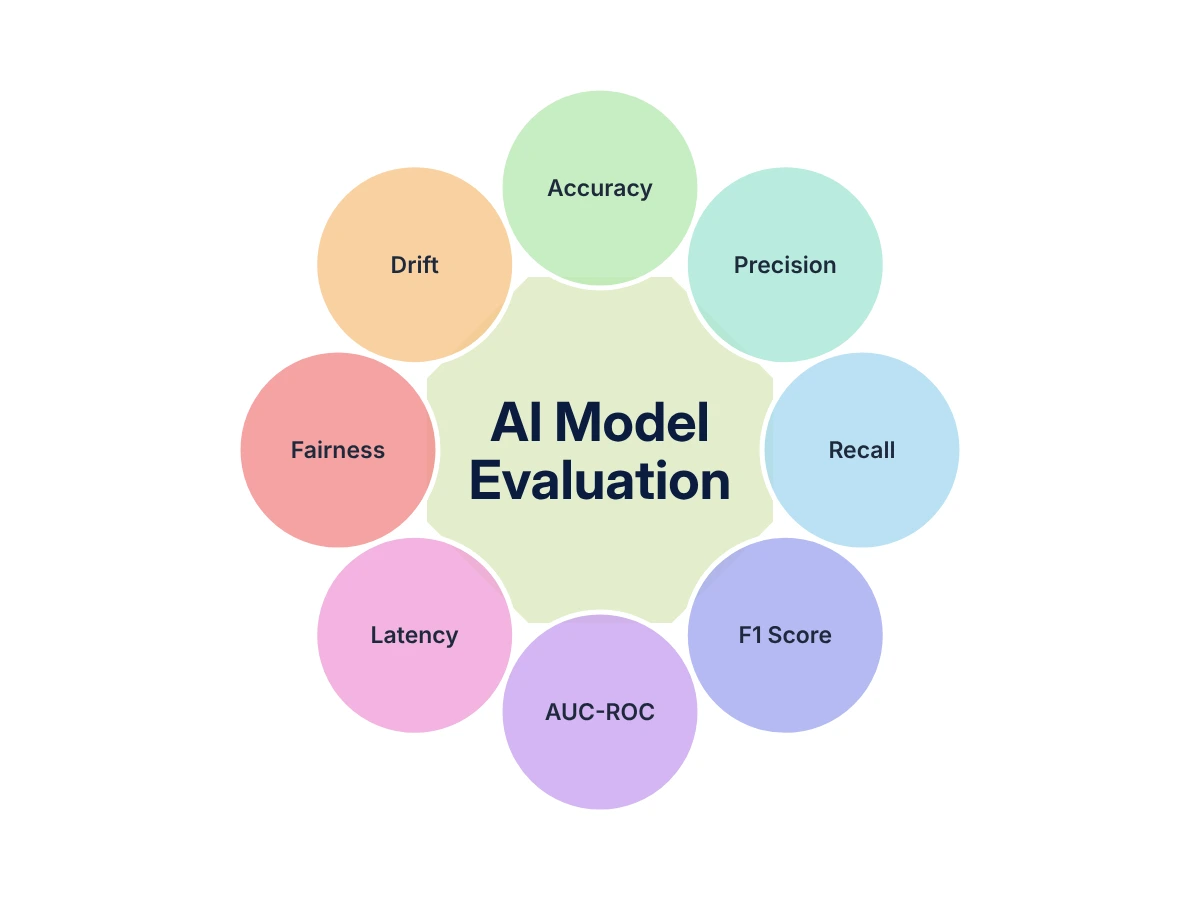
The right metrics depend on what the model does. Here are the most widely used AI model evaluation metrics, grouped by task.
Classification models assign inputs to categories, such as fraud or not fraud, or positive, neutral, or negative sentiment.
| Metric | What It Measures | When to Use It |
|---|---|---|
| Accuracy | Share of all predictions that are correct | Balanced classes with similar error costs |
| Precision | Of the items flagged positive, how many really are positive | When false alarms are costly, such as spam filters |
| Recall | Of all real positives, how many the model found | When missed cases are costly, such as fraud or disease detection |
| F1 score | Harmonic mean of precision and recall | Imbalanced data where both error types matter |
| AUC-ROC | How well the model separates classes across all thresholds | Comparing models before choosing a threshold |
| PR-AUC | Precision and recall trade-off across thresholds | Highly imbalanced data with a rare positive class |
| Log loss | How confident and correct the predicted probabilities are | When probability scores drive decisions |
The core formulas are simple. With TP as true positives, FP as false positives, and FN as false negatives:
Always review the confusion matrix too. It shows exactly which classes the model mixes up, which a single score cannot.
Regression models predict numbers, such as demand, prices, or delivery times.
For computer vision tasks, metrics measure both what the model sees and where it sees it:
Traditional text metrics compare model output with reference answers:
These metrics are fast and cheap, but they struggle with open-ended outputs where many different answers can be correct. That is why modern LLM evaluation relies on the metrics below.
For chatbots, copilots, and RAG systems, quality depends on whether answers are correct, grounded, and useful:
| Metric | What It Checks |
| Faithfulness (groundedness) | Whether every claim in the answer is supported by the retrieved context |
| Answer relevance | Whether the answer actually addresses the question asked |
| Context precision and recall | Whether retrieval found the right documents and ranked them well |
| Hallucination rate | Share of responses that contain unsupported or false statements |
| Correctness | Agreement with a verified reference answer |
| Instruction following | Whether the output respects format, tone, length, and policy rules |
| Toxicity and safety | Whether the output contains harmful, biased, or disallowed content |
Evaluating retrieval and generation separately is important. If an answer is wrong, you need to know whether the retriever missed the right document or the model ignored it.
AI agents take actions across tools and systems, so they are judged on outcomes, not just text:
Every production model should also be measured on:
For self-hosted LLMs, the serving engine has a big effect on these numbers. Our comparison of SGLang vs vLLM covers this in detail.
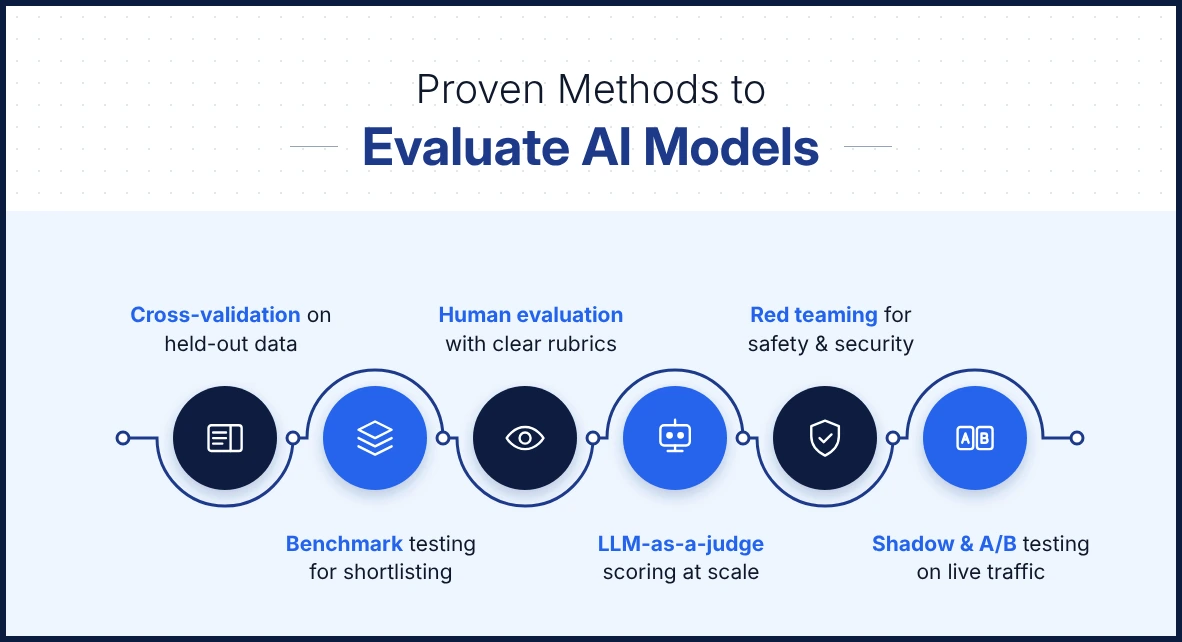
Metrics tell you what to measure. Methods tell you how to evaluate AI models in a way you can trust, from early development through live traffic.
| Method | How It Works | Best For |
|---|---|---|
| Holdout split | Separate training, validation, and test sets | Large datasets and quick comparisons |
| K-fold cross-validation | Train and test on several different splits, then average results | Smaller datasets and more stable estimates |
| Time-based split | Train on past data and test on later data | Forecasting and any data that changes over time |
| Benchmark testing | Score the model on public datasets such as MMLU or HumanEval | Shortlisting foundation models |
| Human evaluation | Experts rate outputs using a clear rubric | Open-ended outputs and high-stakes domains |
| LLM-as-a-judge | A strong model scores outputs against a rubric | Scaling LLM evaluation across thousands of samples |
| Red teaming | Testers deliberately try to make the model fail or misbehave | Safety, security, and prompt injection testing |
| Shadow deployment | The new model runs on live traffic without affecting users | Low-risk validation before rollout |
| A/B testing | Compare models on business KPIs with real users | Proving business impact |
| Production monitoring | Track quality, drift, and cost continuously after launch | Every model in production |
Two of these methods need extra care. Public benchmarks are useful for shortlisting, but models may have seen benchmark questions during training, and a high benchmark score does not guarantee good results on your data. LLM-as-a-judge scales well, but judge models can favor longer answers, answers in a certain position, or outputs from their own model family. Calibrate the judge against a sample of human ratings before relying on it.
Also Read: Production RAG Architecture
Large language models break several assumptions that classic machine learning evaluation relies on:
| Aspect | Traditional ML | LLMs |
|---|---|---|
| Output | A label or number | Open-ended text, code, or actions |
| Correct answer | Usually one | Often many valid answers |
| Consistency | Same input gives the same output | Outputs can vary between runs |
| Main scoring | Automated metrics | Rubrics, LLM judges, and human review |
| What can change | Mainly the model and data | Model version, prompts, retrieval, and tools |
In practice, this means LLM evaluation should use clear scoring rubrics, run each test case more than once, and keep a regression suite that re-runs automatically whenever a prompt, retrieval setting, or model version changes. When you fine-tune an LLM, compare it against the base model on the same suite to confirm the gains are real and that general abilities have not dropped.
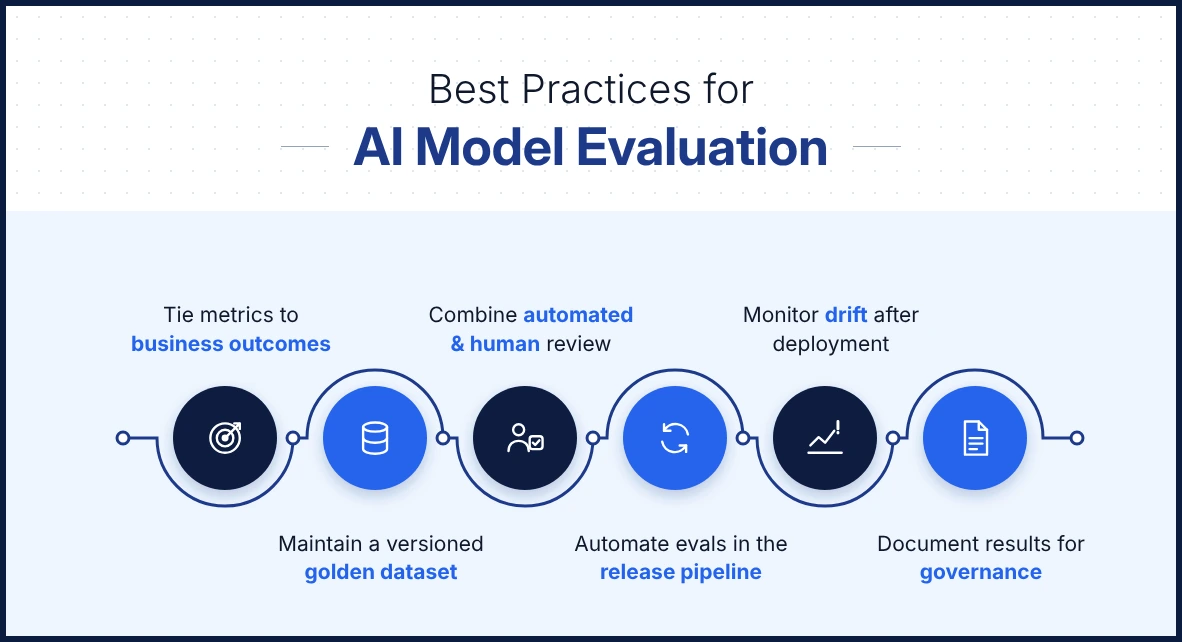
Teams that evaluate AI models well tend to follow the same habits. These practices keep evaluation consistent as models, data, and prompts change.
Translate model metrics into terms stakeholders understand, such as fraud losses prevented, support tickets resolved, or hours of manual review saved. This makes trade-off decisions clearer and easier to defend.
Keep a curated, versioned test set that grows over time. Add every important production failure to it so the same mistake is caught automatically in future releases.
Use automated metrics and LLM judges for scale, and domain experts for nuance and high-risk cases. Review a sample of automated scores by hand regularly to make sure they still match human judgment.
Run the evaluation suite automatically on every model, prompt, or data change, and block releases that fall below agreed thresholds. Strong MLOps practices make this repeatable instead of a manual check before launch.
Track input data drift with measures such as the population stability index (PSI), watch prediction distributions, and collect user feedback signals such as corrections, thumbs-down ratings, and escalations to a human. Set alerts so the team investigates before users notice a drop.
Record what was tested, with which data, and with what results in model cards or evaluation reports. Frameworks such as the NIST AI Risk Management Framework and ISO/IEC 42001 expect this kind of evidence, and AI governance consulting can help you set it up in a way that satisfies auditors.
You do not need to build evaluation tooling from scratch. Widely used options include:
Knowing how to evaluate AI models is what separates a promising prototype from a dependable product. Define success in business terms, test on representative data, choose metrics that fit the task, and look beyond quality scores to fairness, robustness, latency, and cost. Then keep measuring after launch, because a model that works today can drift tomorrow.
With 20+ years of software delivery and 1,800+ projects completed, Xicom helps businesses build AI they can trust. Whether you need an independent AI audit of an existing system or end-to-end AI development services with evaluation built in from day one, our team can help.
To evaluate an AI model, define business success criteria, test the model on held-out data that reflects real usage, and measure task-specific metrics such as precision, recall, or faithfulness. Then check robustness, fairness, latency, and cost, validate with real users through shadow or A/B testing, and monitor the model continuously in production.
It depends on the task. Classification models use precision, recall, F1 score, and AUC-ROC. Regression models use MAE, RMSE, and R squared. LLMs and RAG systems use faithfulness, answer relevance, and hallucination rate. Every production model should also be measured on latency and cost per request.
Accuracy can be misleading when classes are imbalanced. If only 1% of transactions are fraud, a model that never flags fraud is still 99% accurate. Precision, recall, and F1 score show how well the model handles the cases that actually matter.
LLMs are evaluated with a mix of reference-based metrics, rubric-based scoring by human experts or an LLM judge, and task metrics such as faithfulness, correctness, and hallucination rate. Teams also run safety and red-team tests, repeat test cases to account for varied outputs, and re-run a regression suite whenever prompts or model versions change.
LLM-as-a-judge is an evaluation method where a strong language model scores another model’s outputs against a defined rubric. It scales much better than human review, but judge models can be biased toward longer or self-similar answers, so their scores should be calibrated against a sample of human ratings.
Model drift is the gradual drop in model performance as real-world data or user behavior changes after deployment. It is detected by monitoring input data distributions with measures such as the population stability index, tracking prediction patterns and quality metrics, and watching user feedback signals.
AI models should be monitored continuously in production and fully re-evaluated whenever the model is retrained, a prompt or retrieval setting changes, the provider releases a new model version, or monitoring shows a meaningful drop in quality.
Based on this article's topic
AI app development cost ranges from $30,000 to $300,000+. See costs by complexity and use case, running costs, timelines, and tips to cut your budget.
Learn how AI in treasury management improves cash forecasting, reconciliation, payments, and fraud detection, plus the key challenges and how to implement it.
Compare SGLang vs vLLM on architecture, benchmarks, GPU cost and real workloads to pick the right LLM inference engine for your production AI stack.