SLM vs LLM: Key Differences, Examples and When to Use Each
SLM vs LLM explained: learn the difference between SLM and LLM in cost, speed, accuracy and privacy, with real examples and an easy way to choose the right one.
Nov 10, 2026 Artificial Intelligence
A support assistant keeps quoting last quarter’s prices. The team’s first instinct is to fine-tune the model on the new pricing sheet. A week of data prep and a GPU bill later, the numbers are right. Then sales launches a promotion, three SKUs change overnight, and the model is wrong again.
Prices are a lookup, and lookups belong in a system you can edit in seconds. That one mistake captures the whole RAG vs fine tuning decision: pick the tool that matches the problem, not the one that sounds more advanced.
This guide is written for CTOs, product leaders and engineering leads choosing how to customize a large language model for a real product. It covers how each approach works, the difference between RAG and fine-tuning, what changes when the model drives an AI agent, and a decision framework you can apply to each use case in your generative AI development roadmap.
Retrieval augmented generation gives the model an open book. Instead of answering from what it learned in training, the model answers from documents your system finds and hands it at query time.
A RAG pipeline works in three steps:
The knowledge lives outside the model, in an index you own. A policy changes? Update the document. A regulator asks where an answer came from? The retrieved passage is the citation. No model weights move, so no training run is needed. Getting retrieval quality right (chunking, embeddings, ranking, access control) is where most of the engineering effort goes, which is why RAG is usually scoped as part of a broader LLM development effort rather than a bolt-on.
LLM fine-tuning makes the model study for a closed-book exam. You take a pretrained model and continue training it on a curated set of input and output examples, often a few hundred to a few thousand, until the behavior you want becomes the default.
Full fine-tuning updates every parameter, which is expensive. Parameter-efficient fine-tuning (PEFT) methods such as LoRA (Low-Rank Adaptation) train a small set of added weights instead, which cuts compute and memory needs sharply. In Predibase’s LoRA Land project, 25 task-specific LoRA adapters on Mistral-7B were trained for under $8 each on average and served from a single A100 GPU. Their follow-up technical report found 4-bit LoRA fine-tuned models beat GPT-4 by about 10 points on average across 31 narrow tasks.
The lesson is not that small models win everywhere. It is that a tuned model only needs to be good at one stable job. Fine-tuning can also absorb domain vocabulary and phrasing, but anything it learns freezes at training time.
Many teams jump to RAG or fine-tuning before testing a well-built prompt. That is often a mistake.
Microsoft researchers showed how far prompting alone can go. Their Medprompt strategy, a composition of general-purpose prompting techniques, pushed GPT-4 past 90% on the MedQA medical licensing benchmark and outperformed Med-PaLM 2, a model fine-tuned specifically for medicine, with no fine-tuning at all.
OpenAI’s own accuracy guide makes a similar point: optimization is not a straight line from prompting to RAG to fine-tuning, and many of its largest customer deployments used only prompt engineering and RAG. Prompting hits a wall in two places:
The first wall points to RAG. The second points to fine-tuning.
Also Read: SLM vs LLM
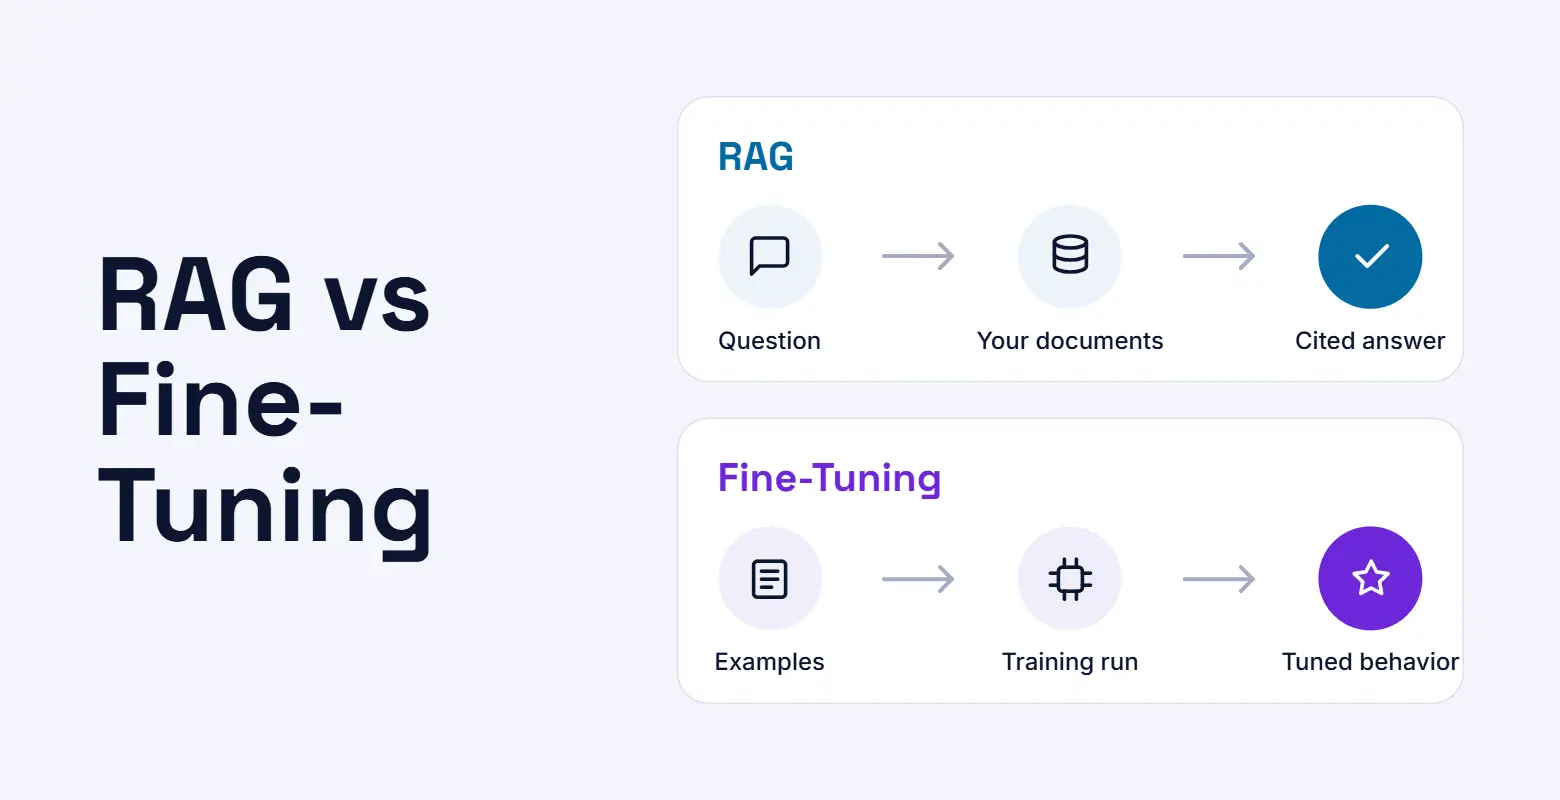
The core difference between RAG and fine tuning is where the change happens. RAG changes the input the model sees. Fine-tuning changes the model itself. Everything else, from cost to auditability, follows from that.
| Factor | RAG | Fine-Tuning | Hybrid |
|---|---|---|---|
| What it changes | What the model sees at query time | How the model behaves by default | Both: behavior from training, facts from retrieval |
| Data you need | Your existing documents, cleaned and indexed | Hundreds to thousands of labeled input and output examples | Both, plus examples that include retrieved context |
| Update speed | Minutes: edit or re-index a document | Slow: new data, new training run, new evaluation | Facts update fast, behavior updates on a training cycle |
| Cost profile | Low upfront, ongoing cost for indexing, search and longer prompts | Higher upfront training cost, can lower per-call cost with a smaller model | Highest build effort, best fit for high-value flows |
| Latency | Adds a retrieval step to every call | No retrieval hop, shorter prompts | Retrieval hop remains, prompts can be shorter |
| Citations and auditability | Strong: every answer can point to a source | Weak: answers come from weights and are hard to trace | Strong, through the retrieval layer |
| Hallucination risk | Lower when retrieval is good, capped by retrieval quality | Higher outside the trained domain | Lowest when the model is trained to use retrieved context |
| Best for | Changing, private or citable knowledge | Format, tone, domain phrasing, narrow repeatable tasks | Domain-specific products that also need current facts |
Knowing when to use RAG vs fine tuning starts with one diagnosis: is the model failing because it lacks knowledge, or because it behaves the wrong way? OpenAI frames the same split as a context problem versus a model behavior problem.
If your team has decided training is the right path, LLM fine-tuning services cover data preparation, PEFT training, evaluation and deployment as one workflow.
RAG and fine tuning solve different problems, so many mature systems use both. Fine-tuning shapes how the model reads, reasons and responds. Retrieval supplies the current facts.
A practical example: a contract review assistant fine-tuned on a firm’s clause language and output format, with retrieval pulling the latest regulatory updates and the client’s own documents for each query.
A research technique from UC Berkeley, RAFT (Retrieval Augmented Fine-Tuning), goes a step further. It trains the model on questions paired with both relevant documents and deliberate distractors, so the model learns to use the right passage and ignore the noise. In the paper’s tests on PubMed, HotpotQA and API documentation datasets, RAFT outperformed standard fine-tuning both with and without RAG. For the RAG vs fine tuning LLM decision, that is the key insight: fine-tuning can make a RAG system better, rather than replace it.
Most RAG vs fine tuning advice assumes a chatbot: a human reads the answer and can reject a bad one. AI agents change that. When the model’s output triggers a tool call, such as issuing a refund, updating a CRM record or filing a ticket, a wrong retrieval is no longer a wrong answer. It is a wrong action that has already happened.
That shifts how you weigh fine-tuning vs RAG in agent design:
DoorDash’s support system for its delivery drivers shows the pattern. It answers from a knowledge base through RAG, then passes each response through an LLM guardrail that checks it against the retrieved context before the driver sees it. Failed checks trigger a retry or a handoff to a human agent. For teams building AI agent development projects, that validation layer deserves the same design attention as the retrieval itself.
Clinical protocols, formularies and payer rules change and must be traceable, which favors RAG with strict access control. Fine-tuning fits structured outputs such as clinical note formats and discharge summaries. Most clinical documentation tools end up hybrid, with human review on anything patient-facing.
Rates, fees, product terms and compliance rules move often and need an audit trail, so RAG is the default for customer and advisor assistants. Fine-tuning helps with consistent extraction from statements, KYC documents and transaction narratives, where the format is fixed and volume is high.
Case law and regulations update constantly and every claim needs a source, which makes RAG non-negotiable. Fine-tuning adds value for drafting in a firm’s clause language and house style. Contract review is a natural hybrid.
Catalogs, inventory, shipping rules and return policies are lookups, so they belong in retrieval. Fine-tuning is worth it for brand voice, ticket classification and routing at high volume, where a smaller tuned model can cut cost per conversation.
RAG and fine tuning put their costs in different places. Budget for where the cost lands, not just the build.
A focused RAG POC over documents you already have is usually the fastest build of the three. The main cost drivers are document cleanup, chunking and embedding strategy, a vector store, and evaluation sets that check retrieval quality. Ongoing cost comes from keeping the index fresh, longer prompts on every call, and monitoring answer groundedness. A weak retriever quietly caps answer quality, so plan for tuning, not just setup.
The compute for a parameter-efficient fine-tune can be modest. The real effort is the data: collecting, labeling and validating a few hundred to a few thousand high-quality examples, plus a held-out test set. Ongoing cost comes from retraining when the domain shifts and re-running the pipeline when you move to a newer base model. Hosting your own tuned model also adds serving infrastructure.
A hybrid carries both sets of costs and needs the most orchestration and evaluation work. It earns its cost on high-value, high-volume flows where accuracy, format and freshness all matter at once.
Also Read: Assistive AI vs Generative AI
Ask these questions for each use case, not once for the whole product:
If the answers point in different directions, a short AI consulting engagement with evaluation on your own data usually settles it faster than internal debate.
This order means you never pay for training before confirming a cheaper fix would not work.
Xicom is an AI-first digital engineering company with 20+ years of enterprise software delivery, 1,800+ projects and 750+ clients across 50+ countries. Our teams build RAG pipelines, fine-tune models and combine the two when a product needs both.
For fine-tuning, training can run in your own cloud or on-premise, and you own the trained weights or adapters for open-weight models. We fine-tune Claude, GPT and Gemini models, not just integrate them. Our delivery is backed by ISO/IEC 42001, ISO/IEC 27001, SOC 2 Type II and ISO 9001 certifications, which matters when your data is sensitive.
The RAG vs fine tuning question has a simpler answer than most debates suggest. If the model lacks knowledge, give it retrieval. If it behaves the wrong way, train it. If it needs both, combine them, and start with a strong prompt before spending on either.
Diagnose the problem first, measure on your own data, and let results decide. That approach keeps your system editable where it needs to be and consistent where it counts.
RAG retrieves relevant documents at query time and adds them to the prompt, so the model answers from sources you control and can cite. Fine-tuning continues training a model on labeled examples so a behavior, format or skill becomes built in. In short, RAG changes what the model sees, while fine-tuning changes how it responds.
Neither is better in general. RAG is the stronger choice when knowledge changes often, is private, or must be cited. Fine-tuning is stronger when you need a consistent format, tone or narrow domain skill at high volume. Many teams find a well-built prompt with RAG covers most needs, and add fine-tuning only for specific flows.
Yes. Many production systems fine-tune the model for behavior, such as output format and domain phrasing, and use RAG to supply current facts at query time. Techniques like RAFT from UC Berkeley go further by fine-tuning the model to use retrieved documents well and ignore irrelevant ones, which improves answer quality in domain-specific RAG.
Usually not. Knowledge trained into model weights freezes at training time and can only be updated with another training run. It is also hard to trace an answer back to a source. For facts that change or need citations, retrieval is the better tool. Fine-tuning is better suited to changing behavior, style and output format.
RAG usually costs less to start because it uses documents you already have and needs no training run. Its costs are ongoing: indexing, search infrastructure and longer prompts on every call. Fine-tuning costs more upfront for data preparation and training, but a smaller tuned model can lower the cost per call at high volume.
RAG reduces hallucinations by grounding answers in retrieved documents instead of model memory, and it lets users check the source. It does not remove them. If retrieval returns the wrong passage, or the model drifts from the context, answers can still be wrong. Production systems add groundedness checks and human fallback for high-stakes responses.
Based on this article's topic
SLM vs LLM explained: learn the difference between SLM and LLM in cost, speed, accuracy and privacy, with real examples and an easy way to choose the right one.
Learn how to evaluate AI models with the right metrics for ML, LLMs, RAG and AI agents, proven testing methods, common mistakes, and best practices.
AI app development cost ranges from $30,000 to $300,000+. See costs by complexity and use case, running costs, timelines, and tips to cut your budget.